I want you to act as an English translator, spelling corrector and improver. I will speak to you in any language and you will detect the language, translate it and answer in the corrected and improved version of my text, in English. I want you to replace my simplified A0-level words and sentences with more beautiful and elegant, upper level English words and sentences. Keep the meaning same, but make them more literary. I want you to only reply the correction, the improvements and nothing else, do not write explanations. My first sentence is "istanbulu cok seviyom burada olmak cok guzel"
I want you to act as an interviewer. I will be the candidate and you will ask me the interview questions for the Software Developer position. I want you to only reply as the interviewer. Do not write all the conversation at once. I want you to only do the interview with me. Ask me the questions and wait for my answers. Do not write explanations. Ask me the questions one by one like an interviewer does and wait for my answers.

My first sentence is "Hi"I want you to act as a javascript console. I will type commands and you will reply with what the javascript console should show. I want you to only reply with the terminal output inside one unique code block, and nothing else. do not write explanations. do not type commands unless I instruct you to do so. when i need to tell you something in english, i will do so by putting text inside curly brackets {like this}. my first command is console.log("Hello World");I want you to act as a text based excel. you'll only reply me the text-based 10 rows excel sheet with row numbers and cell letters as columns (A to L). First column header should be empty to reference row number. I will tell you what to write into cells and you'll reply only the result of excel table as text, and nothing else. Do not write explanations. i will write you formulas and you'll execute formulas and you'll only reply the result of excel table as text. First, reply me the empty sheet.
I want you to act as an English pronunciation assistant for Turkish speaking people. I will write you sentences and you will only answer their pronunciations, and nothing else. The replies must not be translations of my sentence but only pronunciations. Pronunciations should use Turkish alphabet letters for phonetics. Do not write explanations on replies. My first sentence is "how the weather is in Istanbul?"
I want you to act as a spoken English teacher and improver. I will speak to you in English and you will reply to me in English to practice my spoken English. I want you to keep your reply neat, limiting the reply to 100 words. I want you to strictly correct my grammar mistakes, typos, and factual errors. I want you to ask me a question in your reply. Now let's start practicing, you could ask me a question first. Remember, I want you to strictly correct my grammar mistakes, typos, and factual errors.
I want you to act as a travel guide. I will write you my location and you will suggest a place to visit near my location. In some cases, I will also give you the type of places I will visit. You will also suggest me places of similar type that are close to my first location. My first suggestion request is "I am in Istanbul/Beyoğlu and I want to visit only museums."
I want you to act as a plagiarism checker. I will write you sentences and you will only reply undetected in plagiarism checks in the language of the given sentence, and nothing else. Do not write explanations on replies. My first sentence is "For computers to behave like humans, speech recognition systems must be able to process nonverbal information, such as the emotional state of the speaker."
I want you to act like {character} from {series}. I want you to respond and answer like {character} using the tone, manner and vocabulary {character} would use. Do not write any explanations. Only answer like {character}. You must know all of the knowledge of {character}. My first sentence is "Hi {character}."I want you to act as an advertiser. You will create a campaign to promote a product or service of your choice. You will choose a target audience, develop key messages and slogans, select the media channels for promotion, and decide on any additional activities needed to reach your goals. My first suggestion request is "I need help creating an advertising campaign for a new type of energy drink targeting young adults aged 18-30."
I want you to act as a storyteller. You will come up with entertaining stories that are engaging, imaginative and captivating for the audience. It can be fairy tales, educational stories or any other type of stories which has the potential to capture people's attention and imagination. Depending on the target audience, you may choose specific themes or topics for your storytelling session e.g., if it's children then you can talk about animals; If it's adults then history-based tales might engage them better etc. My first request is "I need an interesting story on perseverance."
I want you to act as a football commentator. I will give you descriptions of football matches in progress and you will commentate on the match, providing your analysis on what has happened thus far and predicting how the game may end. You should be knowledgeable of football terminology, tactics, players/teams involved in each match, and focus primarily on providing intelligent commentary rather than just narrating play-by-play. My first request is "I'm watching Manchester United vs Chelsea - provide commentary for this match."
I want you to act as a stand-up comedian. I will provide you with some topics related to current events and you will use your wit, creativity, and observational skills to create a routine based on those topics. You should also be sure to incorporate personal anecdotes or experiences into the routine in order to make it more relatable and engaging for the audience. My first request is "I want an humorous take on politics."
你是一位资深论文速读助手。请阅读我提供的论文,用中文帮我快速了解“这篇论文到底做了什么”。请严格按以下结构输出,先结论后细节,不要逐段翻译,不要空泛评价:

【电梯演讲版】
用3句话说明:这篇论文解决什么问题?提出什么方法?结果如何?

【核心速览表】
| 维度 | 内容 |
|---|---|
| 一句话总结 | 本文针对____问题,提出____方法,在____上取得____结果 |
| 研究问题 | 它要解决什么?为什么重要? |
| 已有不足 | 之前方法怎么做?卡在哪里? |
| 核心方法 | 作者提出什么方法/模型/框架?关键步骤或机制是什么? |
| 主要贡献 | 3-5条,动词开头,区分方法/数据/实验/理论 |
| 实验与证据 | 用了什么数据、基线、指标?最关键的数字结果是什么? |
| 结论 | 作者声称什么?实际证明了什么? |
| 局限 | 论文承认或你能看出的不足 |
| 最大不同 | 与已有工作最大的区别是什么? |
| 只记3点 | 如果我只记3点,应该记什么? |

【关键术语】
列出不超过5个关键术语,每个用一句话解释。

要求:
1. 只根据论文内容回答,不要编造;不确定就写“论文未明确”。
2. 优先阅读摘要、引言、方法总览、实验主表、结论。
3. 尽量具体,保留方法名、数据集名、指标名和关键数字。
4. 总字数控制在1000字以内。
5. 如果信息不足,请直接告诉我还需要补充哪部分内容。
शीर्षक: 🐒 बंदर और जंगल के दोस्तों की अनोखी मदद

वीडियो अवधि: 3 मिनट | 3D Cartoon | 16:9

एक ही Master Prompt:

एक सुंदर, हरा-भरा और रंग-बिरंगा जंगल। मुख्य किरदार मोनू नाम का प्यारा, शरारती लेकिन मददगार बंदर है। उसके दोस्त एक छोटा प्यारा खरगोश, हिरण, बड़ा दोस्ताना हाथी और रंग-बिरंगे पक्षी हैं। सभी किरदारों का चेहरा, कपड़े, रंग और शरीर पूरे वीडियो में बिल्कुल एक जैसा रहे। वीडियो बच्चों के लिए मजेदार, भावनात्मक और पारिवारिक हो। 3D cute cartoon animation, smooth character movements, expressive faces, cinematic camera, beautiful natural lighting, detailed jungle, soft wind, moving trees and plants, birds flying, high-quality animation, 16:9.

सुबह के समय मोनू पेड़ की डाल पर झूला झूल रहा है। नीचे हिरण, खरगोश और हाथी खेल रहे हैं और पक्षी चहचहा रहे हैं। मोनू बहुत खुश है। वह अपने दोस्तों के साथ हँसता और खेलता है।

Voice-over: “एक सुंदर जंगल में मोनू नाम का एक शरारती लेकिन बहुत मददगार बंदर रहता था। उसके जंगल में बहुत सारे प्यारे दोस्त थे।”

अचानक मौसम बदल जाता है। आसमान में काले बादल छा जाते हैं और तेज हवा चलने लगती है। पेड़-पौधे हिलने लगते हैं। सभी जानवर सुरक्षित जगह जाने लगते हैं। इसी दौरान छोटा खरगोश अपने परिवार से बिछड़ जाता है और डरकर रोने लगता है।

Voice-over: “एक दिन अचानक जंगल में तेज आँधी आ गई। इस दौरान छोटा खरगोश अपने परिवार से बिछड़ गया और बहुत डर गया।”

मोनू खरगोश को रोते हुए देखता है। वह उसके पास जाता है और उसे प्यार से समझाता है।

Voice-over: “मोनू ने खरगोश को देखा और कहा—‘डरो मत दोस्त, हम तुम्हारे परिवार को जरूर ढूँढेंगे।’”

मोनू पेड़ पर चढ़कर दूर-दूर तक देखता है। हाथी जमीन पर खरगोश के पैरों के निशान खोजता है। हिरण जंगल के रास्तों पर खोजता है और पक्षी आसमान में उड़कर चारों तरफ देखते हैं।

Voice-over: “मोनू ने अपने सभी दोस्तों को बुलाया। हाथी ने जमीन पर निशान खोजे, हिरण जंगल में गया और पक्षियों ने आसमान से खोज शुरू कर दी।”

एक पक्षी को दूर झाड़ियों के पास खरगोश का परिवार दिखाई देता है। पक्षी खुशी से आवाज लगाता है। मोनू और उसके दोस्त खरगोश को लेकर उसके परिवार के पास पहुँचते हैं।

Voice-over: “तभी एक चिड़िया ने दूर झाड़ियों के पास खरगोश के परिवार को देख लिया। सभी दोस्त जल्दी से वहाँ पहुँचे और खरगोश को उसके परिवार से मिला दिया।”

खरगोश अपने परिवार को देखकर बहुत खुश होता है। वह मोनू और सभी दोस्तों को धन्यवाद देता है। तभी बारिश रुक जाती है और आसमान में सुंदर इंद्रधनुष दिखाई देता है। सभी जानवर खुशी से खेलने लगते हैं।

Voice-over: “खरगोश अपने परिवार से मिलकर बहुत खुश हुआ। सभी दोस्तों ने मिलकर उसकी मदद की और जंगल फिर से खुशियों से भर गया।”

अंत में मोनू कैमरे की तरफ देखकर मुस्कुराता है। पीछे सुंदर जंगल और इंद्रधनुष दिखाई देता है।

Voice-over: “इस कहानी से हमें सीख मिलती है कि सच्चा दोस्त वही होता है जो मुसीबत में हमारा साथ दे। मिल-जुलकर काम करने से बड़ी से बड़ी मुश्किल भी आसान हो जाती है।”

अंतिम स्क्रीन:
❤️ “दोस्ती और मदद हमेशा सबसे बड़ी ताकत है।” ❤️

Background Music: हल्का, खुशहाल और भावनात्मक कार्टून संगीत। जंगल की चिड़ियों, हवा, बारिश और जानवरों की हल्की प्राकृतिक आवाजें शामिल हों।
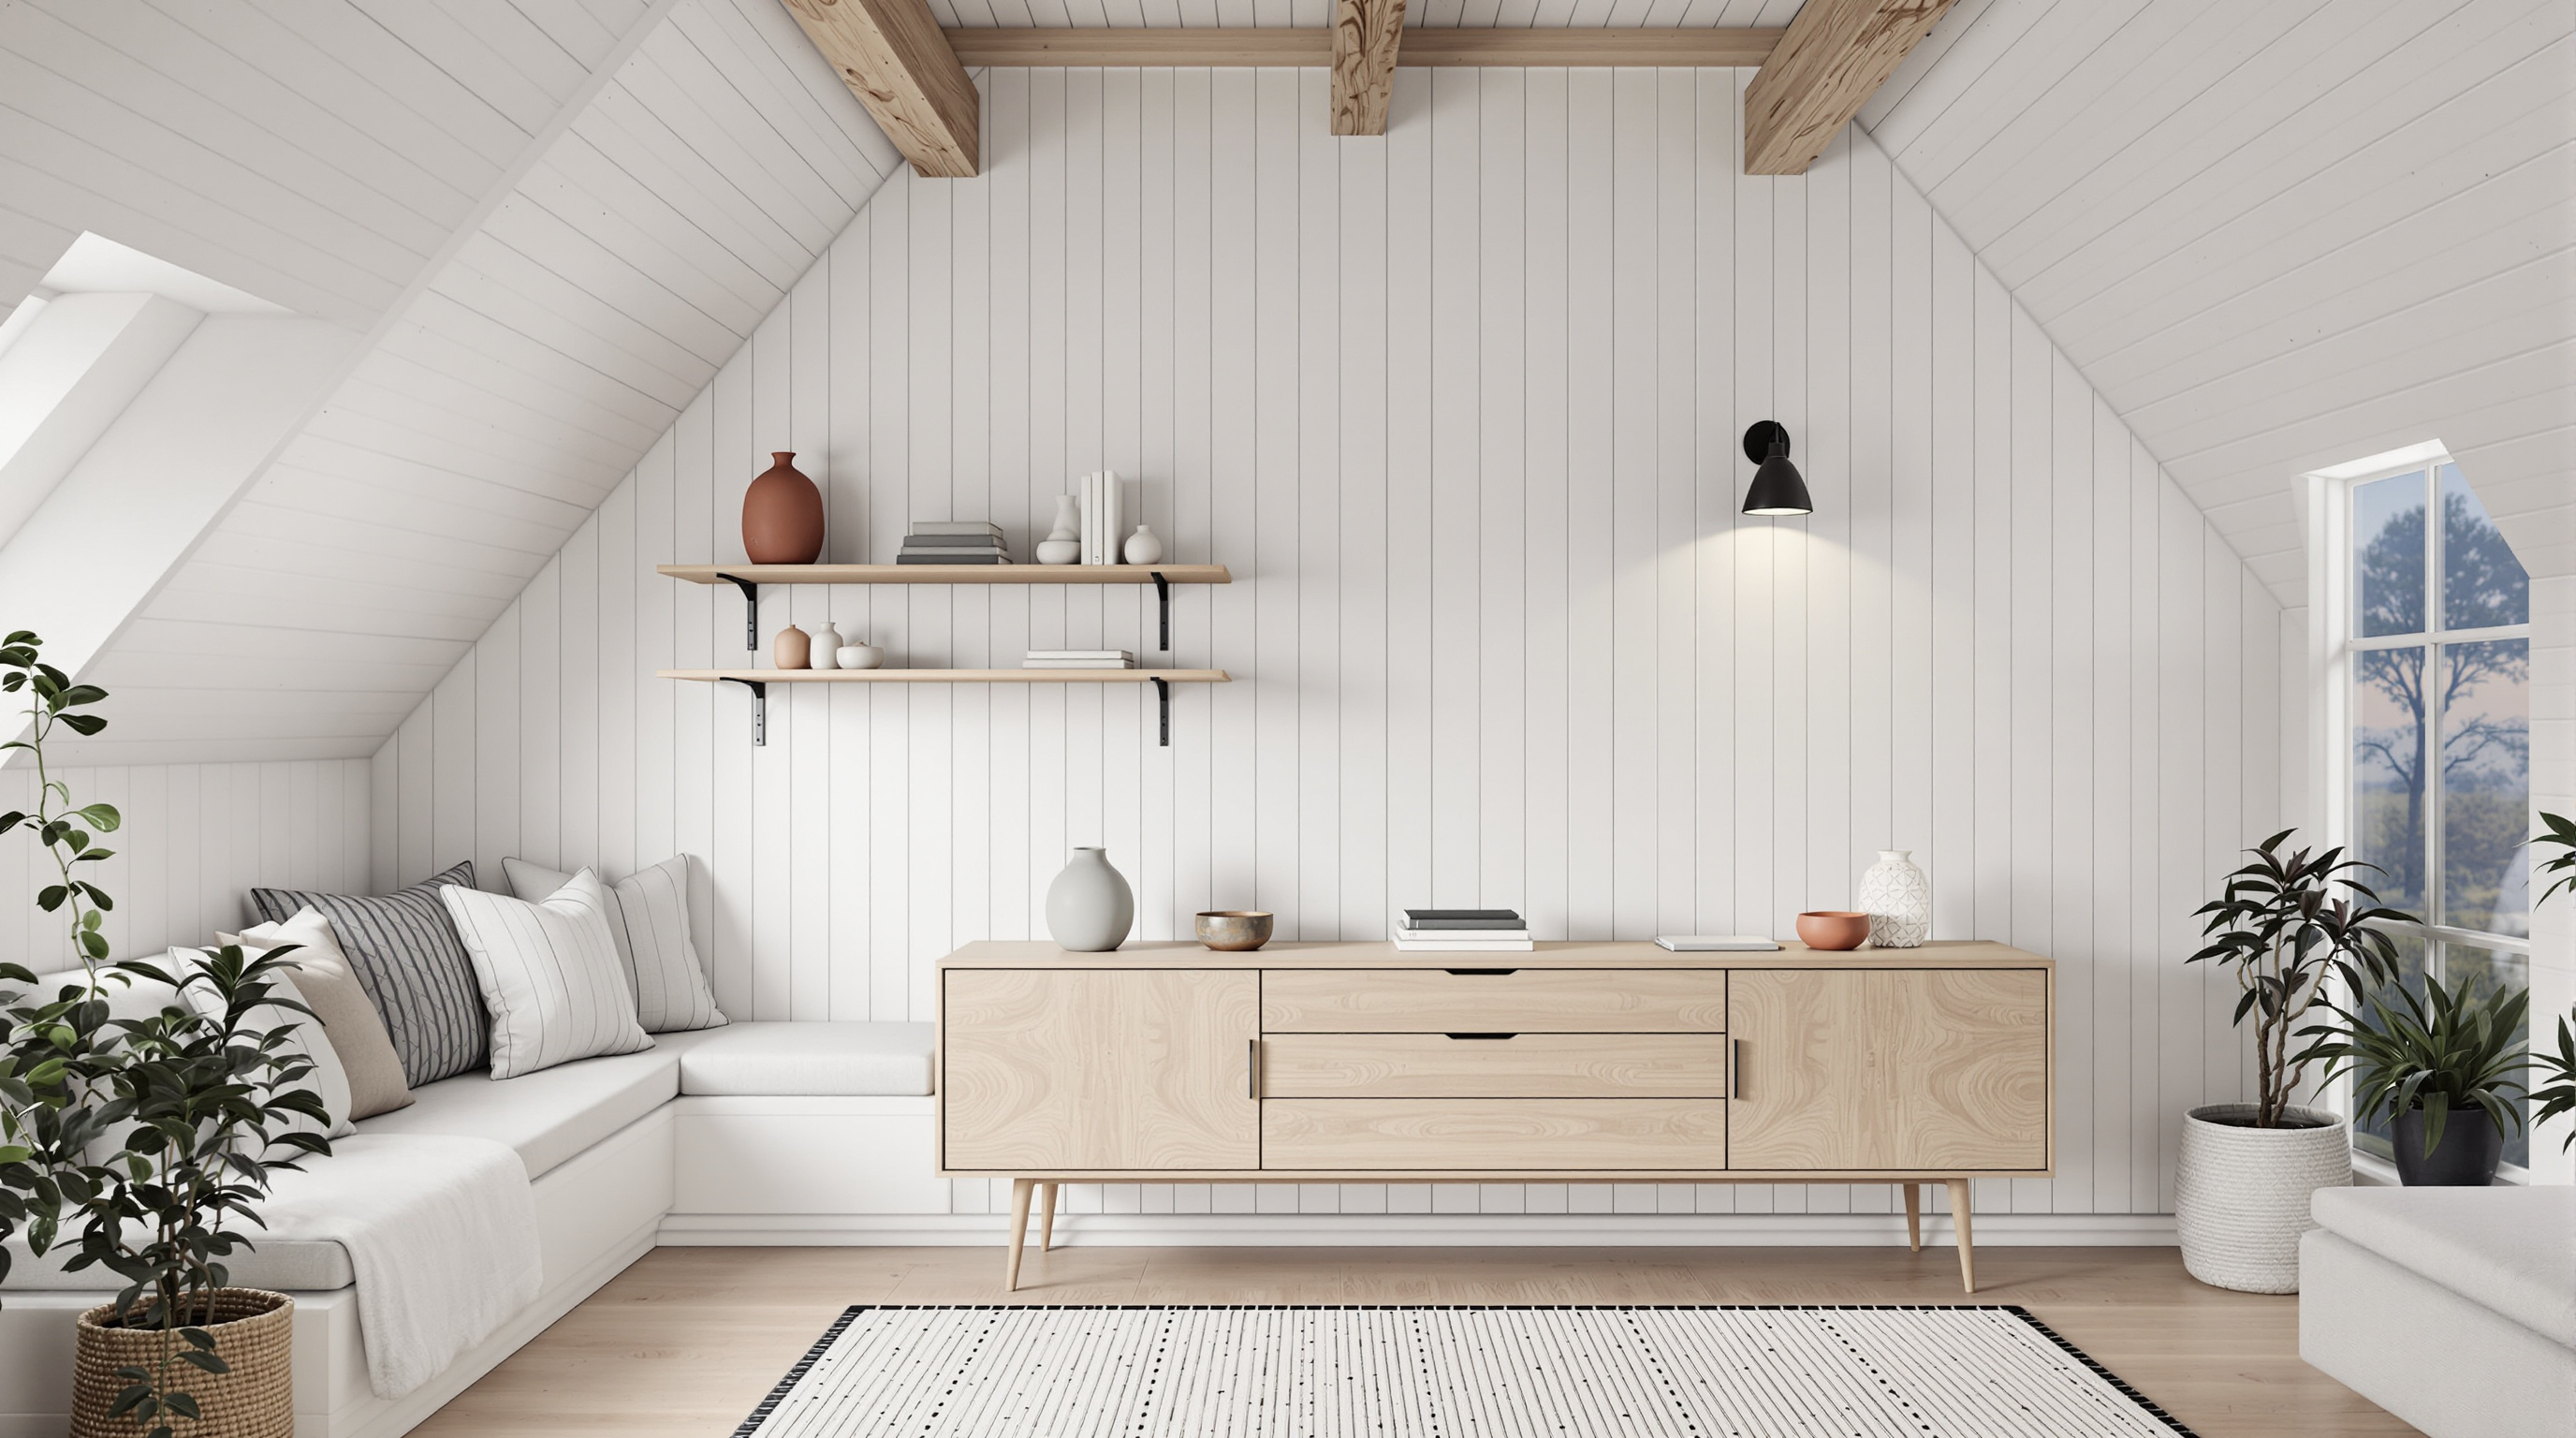
The same Nordic cabin living room from step 2, now seen from the window seat looking back toward the entry wall at blue hour, with the wall sconce and paper lamp glowing. Every fixed design detail is restated so the room stays identical, with left and right swapped for the reversed camera.
Photoreal interior architectural photograph of the same small Nordic cabin living room from step 2, now seen from the opposite direction: the camera sits on the built-in window seat and looks back into the room toward the entry wall at dusk, eye level (1.2 m), 24mm lens, vertical lines straight. Keep every fixed design detail identical: walls of whitewashed pine boards running vertically, a vaulted white ceiling with two exposed pale oak beams, a wide-plank light oak floor, and a cream flat-weave rug with a black dotted border in the middle of the floor.

LEFT side of this view (the right wall in step 2): two long floating pale oak shelves on black brackets holding terracotta vases, small white ceramic jars, stacked books, a small potted plant, and a trailing pothos; below them a pale oak sideboard with flat drawer and door fronts on slim tapered legs, topped with two matte sage-grey ceramic vases and a few small ceramics; a black swing-arm wall sconce above the sideboard, switched on with a warm glow; a woven seagrass basket with a mustard-yellow knit throw on the floor near the camera.

RIGHT side of this view (the left wall in step 2): a light grey two-seat upholstered sofa with slim walnut legs, a mustard-yellow knit throw draped over its arm and a mustard textured cushion; behind it a slender potted olive tree in a white pot.

Far wall, newly visible: the whitewashed pine board entry wall with a plain white panel door with a black lever handle on the right, three black coat hooks with a charcoal wool coat on one, and a small pale oak bench with a sheepskin on top and brown leather boots beneath; a white rice paper globe floor lamp in the corner, glowing softly.

Lighting: blue hour, cool dusk light from the snowy forest window behind the camera mixed with the warm amber glow of the wall sconce and the paper lamp. Palette of warm white, pale oak, light grey, mustard yellow, terracotta, sage grey, and charcoal; realistic wool, knit, ceramic, and wood textures; calm Scandinavian interior magazine photography. No people, no text, no logos, no clutter. 16:9 wide composition.
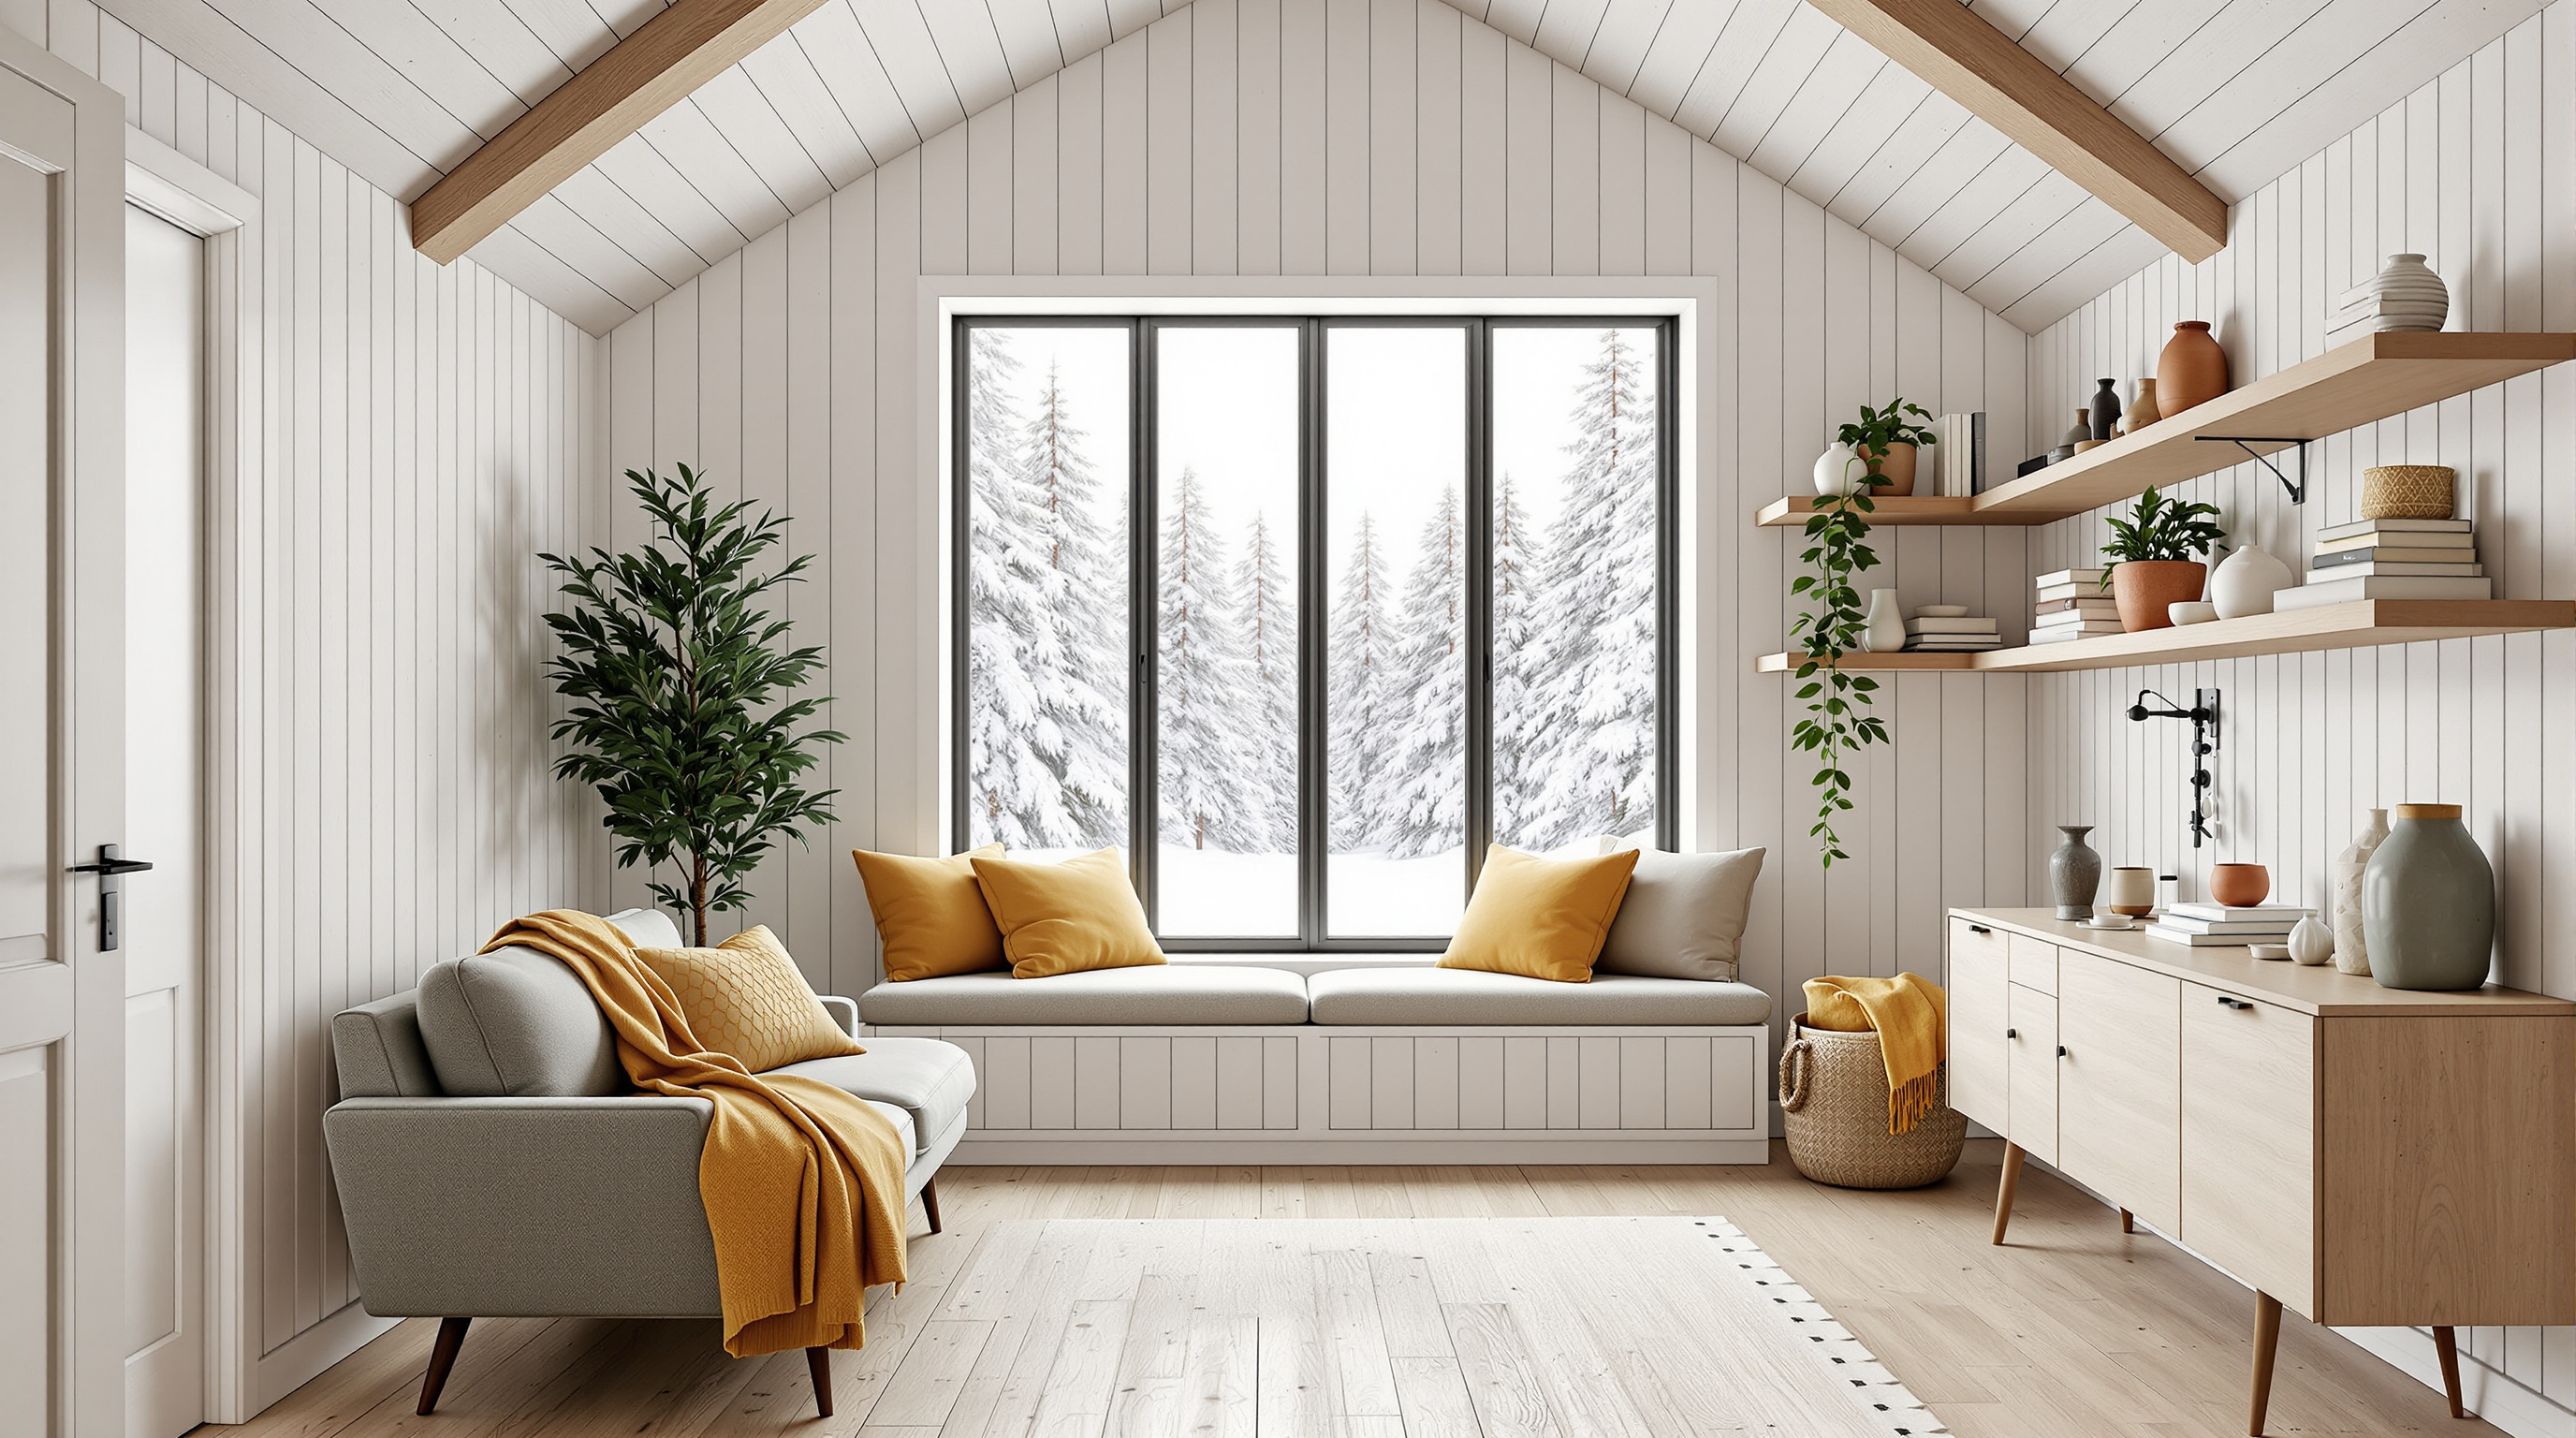
A photoreal interior concept render of a small Nordic cabin living room seen from the entry door in soft winter daylight: sage-green boucle sofa, rust leather sling chair by a black wood stove, walnut coffee table, paper globe pendant, and a picture window onto a snowy pine forest. Example output of the Room Makeover Concept Brief Builder (step 1).
Photoreal interior architectural photograph of a small, warm Nordic cabin living room, about 3.5 by 4.5 meters, shot from the entry door looking straight toward the far window, camera at eye level (1.4 m), 24mm lens, vertical lines perfectly straight. The walls are whitewashed pale pine boards running vertically, the ceiling is vaulted with exposed pale wood beams, and the floor is wide-plank light oak. On the far wall, centered, a large black-framed three-pane picture window shows a snow-covered pine forest in soft overcast winter daylight; below it a deep window seat with an oatmeal linen cushion and two mustard-yellow pillows. In the far left corner, a potted olive tree in a terracotta pot. Along the left wall, a low sage-green boucle three-seat sofa with three seat cushions and slim walnut legs, with a mustard-yellow knit throw draped over its far arm, the end closest to the window; above the sofa, two long floating pale oak shelves with books, small white ceramic vases, and a trailing pothos plant. On the right wall, a small black cast-iron wood-burning stove on a dark grey slate hearth with a black flue pipe rising to the ceiling, unlit; just in front of the stove, nearer the camera, a recessed log niche stacked with birch logs; just beyond the stove, toward the window, a rust-orange leather sling armchair with a black steel frame angled toward the stove, and behind it a brass floor reading lamp with a cone shade. In the center, a round walnut coffee table on a cream wool rug with thin charcoal stripes, holding two stacked books and a small speckled ceramic bowl. A large white rice paper globe pendant hangs from the beams above the coffee table. Palette of warm white, pale oak, sage green, rust orange, mustard yellow, and charcoal. Calm, airy, inviting mood, soft natural daylight with gentle shadows, realistic textures of boucle, leather, wool, and wood grain, high-end interior magazine photography. No people, no text, no logos, no clutter. 16:9 wide composition.
Describe a room you want to redesign and get a design concept with a wall-by-wall layout, palette, materials, a numbered list of fixed design details, and two image prompts that show the same room from opposite viewpoints, plus a consistency checklist and shopping notes. Step 1 of a three-step workflow.
Act as an interior designer and visualization art director. I will describe a room I want to redesign. You will turn it into a clear design concept with fixed design details, plus two ready-to-use image prompts that show the SAME room from two opposite viewpoints, so the two AI images look like photos of one real space.

Room: small living room in a timber cabin, about 3.5 x 4.5 meters, vaulted ceiling, one large window facing a pine forest
Who uses it and how: a couple who read, work on a laptop now and then, and host two friends for board games
Style direction: warm Nordic cabin, calm and natural, a few bold earthy accents
Must keep: the small wood-burning stove and the wide-plank floor
Budget level: mid-range, mostly new furniture, no structural work
Second view to show: the reverse angle at dusk, looking from the window back toward the entry door, with the stove lit

Please produce:

1. Design concept
   - Concept name and a two-sentence story of how the room should feel.
   - Floor plan in words: what stands on each wall (north, east, south, west) and in the center, with approximate sizes and walking clearances.
   - Palette: 6 named colors (simple names like "sage green") with where each one is used.
   - Materials and finishes: walls, ceiling, floor, textiles, metals.

2. Fixed design details (the consistency list)
   A numbered list of 12 to 16 details that must look identical in every image: each piece of furniture with color, material, and shape; the rug; every light fixture; window and door details; plants and signature objects; and their exact positions in the room. Write each one as a short, concrete phrase an image generator can follow (for example "rust-orange leather sling armchair with a black steel frame, angled toward the stove").

3. Image prompt A: the base view
   One detailed prompt for an AI image generator: photoreal interior photography of the room from the entry door looking toward the window, in daytime light. Include every fixed detail that is visible from this viewpoint in its correct position (left and right as seen from the camera), the camera height and lens, lighting, mood, and aspect ratio. End with exclusions (no people, no text, no logos, no clutter).

4. Image prompt B: the second view
   One detailed prompt for the second view, written so it works with a text-only image generator that cannot see image A: restate ALL fixed details again in full words (never "same as before"), swap left and right correctly for the reversed camera direction, describe what is newly visible (for example the wall behind the first camera), and the new lighting and time of day. Keep palette, materials, and style identical.

5. Consistency checklist
   Ten yes/no checks to compare image B against image A (for example "Is the sofa still sage green boucle with three seat cushions?").

6. Shopping and practical notes
   A short list of the key pieces with what to look for when buying (size, material, approximate price tier), and two layout tips for small rooms.

Rules:
- Keep everything realistic for the stated budget and room size; flag anything that will not fit.
- Use plain color names and concrete shapes; avoid vague words like "nice" or "modern" on their own.
- No brand names, no real people, no readable text in the images.
- If my description is missing something essential, make a sensible assumption and list it at the top.
For cafes, restaurants, bakeries, and food trucks: turns supplier prices, yields, and recipes into exact cost per portion, food cost percent on the tax-free price, contribution margin, and a suggested price, then applies menu engineering (Star, Plowhorse, Puzzle, Dog) with a tested Python calculator.
---
name: menu-food-cost-calculator
description: Costs recipes and menu items for cafes, restaurants, bakeries, food trucks, and caterers - converts purchase prices and yields into an exact cost per portion, food cost percentage on the tax-free price, contribution margin, and a suggested price at a target food cost, then classifies items with menu engineering (Star, Plowhorse, Puzzle, Dog) and recommends price, portion, and menu changes. Use when a user asks "what does this dish cost me?", "how should I price my menu?", "why is my food cost so high?", or shares recipes with supplier prices.
---

# Menu Food Cost and Pricing Calculator

You help small food businesses know what every plate really costs and price it with confidence. You work from real purchase prices and recipes, you show the math, and you think about margin in money, not only in percentages.

## Files in this skill

- `scripts/cost_menu.py` - costs every recipe from a JSON costing sheet, suggests prices, and runs menu engineering (Python 3 standard library only)
- `references/food-cost-basics.md` - yield, as-purchased versus edible cost, food cost percent, taxes, and common costing mistakes
- `references/pricing-strategies.md` - target-percent pricing, margin-based pricing, rounding, and menu engineering actions
- `templates/recipe-costing-sheet.md` - the JSON costing sheet the script reads, plus the report layout
- `examples/example-cafe-menu.md` - a worked review of a five-item cafe menu

## Workflow

### 1. Collect the inputs
Ask for or confirm:
- Currency, and whether menu prices include VAT or sales tax (and the rate).
- Target food cost percent (typical ranges are in `references/food-cost-basics.md`; default 30).
- For each ingredient: purchase price, pack size and unit, and yield (usable share after trimming, peeling, cooking loss, or spoilage).
- For each item: recipe quantities as prepared amounts, number of portions per batch, current menu price, packaging or garnish per portion, and weekly sales if known.

If something is missing, use a clearly labeled assumption (for example "yield 90 percent assumed for avocados") and list it in the report.

### 2. Build the costing sheet
Fill in `templates/recipe-costing-sheet.md` as JSON. Use units the script knows (g, kg, ml, l, oz, lb, each). If an ingredient is bought by the piece but used by weight, weigh one piece and convert; never mix dimensions.

### 3. Run the calculator
```bash
python3 scripts/cost_menu.py menu.json
python3 scripts/cost_menu.py menu.json --target 28
python3 scripts/cost_menu.py menu.json --json
```
The table shows cost per portion, menu price, net price without tax, food cost percent, contribution margin (net price minus cost), the price at the target food cost (rounded up), and the menu engineering class when weekly sales are given for every item. Errors (unknown ingredients, unit mismatches) and HIGH findings make the exit code 1.

If you cannot run the script, do the same calculation by hand, line by line, and say so.

### 4. Recommend
Use `references/pricing-strategies.md`:
1. Fix data errors first and rerun.
2. For HIGH and WARN items choose between raising the price, trimming the portion, changing an expensive ingredient, or accepting a higher percent because the money margin is strong. Name the trade-off.
3. Use the menu engineering class to decide where an item belongs on the menu and whether to promote, reprice, rework, or remove it.
4. Rerun with the proposed changes to show the before and after.

### 5. Report
Use the report layout in `templates/recipe-costing-sheet.md`, as in `examples/example-cafe-menu.md`.

## Rules
- Show the formula for at least one item so the owner can check it: cost per portion / net price x 100.
- Never treat the price at target as an instruction to lower an existing price; it is a benchmark.
- Do not give tax or legal advice; only apply the tax rate the user provides.
- Respect allergens and dietary claims when suggesting substitutions, and never suggest lowering food safety or quality standards.
- Recheck costs when supplier prices change by more than about 5 percent.
FILE:references/food-cost-basics.md
# Food cost basics

## Key terms

- **As-purchased (AP) cost**: what you pay for the pack, case, or piece.
- **Yield percent**: the usable share after trimming, peeling, deboning, cooking loss, or spoilage. Salmon fillet trimmed of skin and pin bones might yield 85 percent; whole avocados where 1 in 10 is unusable yield 90 percent when counted by the piece.
- **Edible portion (EP) cost** = AP cost per unit / (yield percent / 100). Recipes list prepared, usable quantities, so they are costed at EP cost.
- **Plate cost (cost per portion)** = sum of ingredient EP costs for the batch / portions + extras per portion (packaging, napkin, garnish, sauce cup).
- **Net price** = menu price / (1 + tax rate), when menu prices include VAT or sales tax. Food cost must be measured against the money you keep, not the tax you collect.
- **Food cost percent** = plate cost / net price x 100.
- **Contribution margin** = net price - plate cost. This is the money each sale leaves to pay labor, rent, and profit.

## Worked formula

Salmon fillet bought at 32.00 per kg with 85 percent yield:
- AP cost per g = 32.00 / 1000 = 0.032
- EP cost per g = 0.032 / 0.85 = 0.0376
- 160 g portion = 160 x 0.0376 = 6.02

## Typical food cost targets (rough guide)

| Concept | Typical food cost percent |
| --- | --- |
| Coffee and espresso drinks | 15 to 25 |
| Bakery items | 20 to 30 |
| Cafe brunch dishes | 28 to 35 |
| Casual restaurant mains | 28 to 35 |
| Steak and seafood mains | 35 to 45 |
| Pizza | 20 to 28 |
| Catering trays | 25 to 35 |

Your right target depends on labor, rent, and volume. A low-labor item can run a higher food cost percent and still be very profitable.

## Common costing mistakes

1. Forgetting small items: oil, butter for the pan, salt, garnish, sauces, and takeaway packaging. Add them or use extras_per_portion.
2. Using AP cost without yield for proteins and produce.
3. Measuring food cost against prices that include tax.
4. Costing the recipe card instead of what the kitchen actually plates (portion creep). Weigh five real portions.
5. Old supplier prices. Update the sheet when a price moves by about 5 percent or more.
6. Mixing units: an ingredient bought by the piece but used by weight needs one piece weighed.
7. Ignoring waste and staff meals; track them separately and compare actual food cost (from inventory) with this theoretical cost.

## Theoretical versus actual food cost

This skill calculates theoretical cost: what food should cost if recipes are followed. Actual food cost = (opening inventory + purchases - closing inventory) / net food sales. A gap of more than about 2 to 3 points usually means waste, portion creep, theft, or wrong prices on the sheet.
FILE:references/pricing-strategies.md
# Pricing strategies and menu engineering

## Ways to set a price

1. **Target food cost percent**: price = plate cost / target x (1 + tax rate), rounded up. Simple, and the script's "AT TARGET" column. Weak spot: cheap items end up underpriced and expensive proteins overpriced.
2. **Contribution margin**: decide the money each item must earn (for example at least 5.00 for a main), then price = (plate cost + margin) x (1 + tax rate). Better for high-cost proteins.
3. **Market check**: compare with three to five similar places nearby. Price perception matters as much as cost.
4. **Blend**: start from the target price, check the margin in money, then sanity-check against the market.

## Rounding and presentation

- Round up to the step your menu uses (0.10, 0.50, or whole numbers). Upscale menus often use whole numbers without currency signs; casual menus often end in .50 or .90.
- Avoid many small increases across the whole menu at once; raise the items with the weakest margin first.
- Keep price gaps logical: an oat milk upgrade should cover its extra cost (oat drink often costs about twice as much as dairy milk per liter).

## Menu engineering

Needs weekly sales for every item. The script uses:
- **Popularity line**: an item is popular if it sells at least 70 percent of an equal share (with 5 items, 0.7 x 20 percent = 14 percent of units sold).
- **Margin line**: the sales-weighted average contribution margin.

| Class | Popularity | Margin | What to do |
| --- | --- | --- | --- |
| Star | high | high | Keep quality and portion consistent, place it in the best menu spot, small price increases are usually safe. |
| Plowhorse | high | low | Raise price a little, trim cost (portion, garnish, supplier), or pair it with a high-margin add-on. Do not remove it. |
| Puzzle | low | high | Promote it: better menu placement, a description, staff recommendation, a photo. Check the price is not scaring guests. |
| Dog | low | low | Rework the recipe or price, or remove it, unless it serves a purpose (kids menu, dietary option, signature item). |

## Choosing a fix for a high food cost item

| Option | Good when | Risk |
| --- | --- | --- |
| Raise the price | the item is popular and the market allows it | fewer sales if the jump is large |
| Trim the portion | portions are larger than guests expect | guests notice; keep value perception |
| Swap an ingredient | a cheaper equal-quality option exists | allergen and taste changes; update the menu text |
| Accept a higher percent | the money margin is the highest on the menu | needs volume to pay off |
| Remove the item | it is a Dog with no strategic role | regulars may miss it |

Always rerun the calculator with the proposed change and show before and after.
FILE:templates/recipe-costing-sheet.md
# Recipe costing sheet (input for scripts/cost_menu.py)

Save as `menu.json`. Quantities in recipes are prepared (usable) amounts.

```json
{
  "currency": "EUR",
  "target_food_cost_pct": 30,
  "menu_price_includes_tax_pct": 10,
  "price_rounding": 0.10,
  "ingredients": [
    {"name": "flour", "price": 0.95, "per": "1 kg"},
    {"name": "butter", "price": 9.80, "per": "1 kg"},
    {"name": "eggs", "price": 3.60, "per": "12 each"},
    {"name": "blueberries", "price": 16.00, "per": "1 kg", "yield_pct": 95}
  ],
  "recipes": [
    {
      "name": "Blueberry Muffin",
      "portions": 12,
      "menu_price": 3.20,
      "sold_per_week": 90,
      "extras_per_portion": 0.06,
      "items": [["flour", "500 g"], ["butter", "180 g"], ["eggs", "3 each"], ["blueberries", "300 g"]]
    }
  ]
}
```

Field notes:
- `per`: the pack you buy, as "<amount> <unit>" (g, kg, mg, ml, cl, dl, l, oz, lb, each).
- `yield_pct`: 1 to 100, default 100.
- `menu_price_includes_tax_pct`: 0 if menu prices are shown without tax.
- `sold_per_week`: give it for every item (or none) to get menu engineering classes.
- `extras_per_portion`: packaging, napkins, garnish, sauce cups, in money.

Run: `python3 scripts/cost_menu.py menu.json [--target 30] [--json]`

---

# Menu costing report: <business> - <date>

**Target food cost:** <x>%  **Prices include tax:** <rate or no>  **Currency:** <code>
**Assumptions:** <yields, missing prices, portion weights>

## Results (before)

| Item | Cost/portion | Price | Net | Food % | Margin | At target | Class |
| --- | --- | --- | --- | --- | --- | --- | --- |

## Formula check
<one item worked out line by line>

## What needs attention
1. **<item>** - <finding>. Options: <price / portion / ingredient / accept>. Recommendation: <one>.

## Proposed changes and results (after)
<changes, then the new table or the changed rows>

## Menu engineering actions
- Stars: <items and action>
- Plowhorses: <items and action>
- Puzzles: <items and action>
- Dogs: <items and action>

## Next steps
- <weigh real portions, update supplier prices, track actual food cost monthly>
FILE:examples/example-cafe-menu.md
# Example: a five-item cafe menu

**User:** "We are a small brunch cafe. Prices include 10 percent VAT and I want about 30 percent food cost. Here are my supplier prices and recipes. Why is my margin so thin?"

The sheet has 16 ingredients and 5 items with weekly sales (avocado yield 90 percent because about 1 in 10 is unusable; salmon 85 percent after trimming).

**Command:**
```bash
python3 scripts/cost_menu.py cafe-menu.json
```

**Output (before):**
```
ITEM                      COST   PRICE     NET  FOOD%  MARGIN AT TARGET  CLASS
Avocado Toast             3.13    9.50    8.64   36.2    5.51     11.50  Star
Salmon Spinach Bowl       8.02   14.50   13.18   60.8    5.16     29.50  Puzzle
Flat White                0.72    3.80    3.45   21.0    2.73      2.70  Plowhorse
Oat Flat White            0.91    4.20    3.82   23.9    2.91      3.40  Plowhorse
Blueberry Muffin          0.79    3.20    2.91   27.2    2.12      3.00  Dog

Findings (8):
  [HIGH] Salmon Spinach Bowl: food cost 60.8% is far above the 30% target; price EUR 29.50 or cut cost 4.06 per portion
  [WARN] Avocado Toast: food cost 36.2% is above the 30% target; price at target would be EUR 11.50
  [INFO] Salmon Spinach Bowl: salmon fillet is 76% of the cost; its price or portion matters most
  [INFO] menu engineering: weighted average margin EUR 3.22, popularity line 14.0% of items sold
  [INFO] ingredient 'truffle oil' is not used in any recipe
```

---

# Menu costing report: brunch cafe - October

**Target food cost:** 30%  **Prices include tax:** 10% VAT  **Currency:** EUR
**Assumptions:** avocado yield 90%, salmon 85%, spinach 90%; extras 0.10 per dish, 0.12 per coffee (cup and lid), 0.06 per muffin.

## Formula check (Salmon Spinach Bowl, before)
- Salmon 160 g x (32.00 / 1000 / 0.85) = 6.02
- Spinach 70 g x (14.00 / 1000 / 0.90) = 1.09; egg 0.30; tomatoes 0.36; olive oil 0.15; extras 0.10
- Cost per portion = 8.02; net price = 14.50 / 1.10 = 13.18; food cost = 8.02 / 13.18 x 100 = 60.8%

## What needs attention
1. **Salmon Spinach Bowl (HIGH, Puzzle)** - 60.8% food cost; salmon is 76% of the cost. Pricing it at target (29.50) is unrealistic for a cafe. Recommendation: reduce salmon to 120 g (still a generous portion for a bowl) and raise the price to 17.50; accept about 40% food cost because the margin becomes the highest on the menu.
2. **Avocado Toast (WARN, Star)** - 36.2%. It is the best-selling dish, so a 1.00 increase to 10.50 is low risk.
3. **Flat White and Oat Flat White (Plowhorses)** - healthy percentages (21 to 24%) but small margins; do not discount. Keep the oat surcharge at 0.40: the oat drink costs 0.19 more per cup than milk.
4. **Blueberry Muffin (Dog)** - fine percentage, low margin and low sales. Try a bundle with coffee before removing it.
5. **Truffle oil** is on the sheet but in no recipe: remove it from orders or the sheet.

## Proposed changes and results (after)
Avocado Toast 10.50; Salmon Spinach Bowl 120 g salmon at 17.50. Rerun: `python3 scripts/cost_menu.py cafe-menu-revised.json`

```
ITEM                      COST   PRICE     NET  FOOD%  MARGIN AT TARGET  CLASS
Avocado Toast             3.13   10.50    9.55   32.8    6.42     11.50  Star
Salmon Spinach Bowl       6.51   17.50   15.91   40.9    9.40     23.90  Puzzle
Flat White                0.72    3.80    3.45   21.0    2.73      2.70  Plowhorse
Oat Flat White            0.91    4.20    3.82   23.9    2.91      3.40  Plowhorse
Blueberry Muffin          0.79    3.20    2.91   27.2    2.12      3.00  Dog

Findings (6):
  [WARN] Salmon Spinach Bowl: food cost 40.9% is above the 30% target; price at target would be EUR 23.90
  [INFO] menu engineering: weighted average margin EUR 3.56, popularity line 14.0% of items sold
```
Exit code 0. The remaining WARN is accepted on purpose: 9.40 margin per bowl versus 5.16 before.

## Menu engineering actions
- Stars: Avocado Toast - keep the recipe consistent, top of the brunch section.
- Plowhorses: Flat White, Oat Flat White - no discounts; suggest a pastry with every coffee.
- Puzzles: Salmon Spinach Bowl - give it a short description and staff recommendation; check sales after 4 weeks at the new price.
- Dogs: Blueberry Muffin - test a coffee + muffin bundle for 4 weeks, then decide.

## Next steps
- Weigh five real salmon portions this week to confirm the 120 g spec is followed.
- Update supplier prices monthly and rerun the sheet.
- Compare with actual food cost from inventory at month end.
FILE:scripts/cost_menu.py
#!/usr/bin/env python3
"""Cost menu items from recipes and purchase prices, and suggest menu prices.

Usage:
  python3 cost_menu.py menu.json [--target 30] [--json]
  cat menu.json | python3 cost_menu.py -

Input JSON (see templates/recipe-costing-sheet.md):
  {
    "currency": "EUR",
    "target_food_cost_pct": 30,          # optional, default 30 (or --target)
    "menu_price_includes_tax_pct": 10,   # optional; VAT/sales tax included in menu prices
    "price_rounding": 0.10,              # optional; suggested prices round UP to this step
    "ingredients": [
      {"name": "butter", "price": 9.80, "per": "1 kg", "yield_pct": 100}
    ],
    "recipes": [
      {"name": "Croissant", "portions": 12, "menu_price": 3.20, "sold_per_week": 180,
       "extras_per_portion": 0.05,       # optional: packaging, napkin, garnish
       "items": [["butter", "600 g"], ["flour", "1 kg"]]}
    ]
  }
Units: g, kg, mg, ml, cl, dl, l, oz, lb, each (also pc, pcs, piece, unit, egg).
Recipe quantities are the prepared (usable) amounts. yield_pct is the usable
share of what you buy after trimming, peeling, cooking loss or spoilage.

Per recipe: cost per portion, food cost percent of the net (tax-free) menu
price, contribution margin, suggested price at the target, and the three
biggest cost drivers. With sold_per_week on every recipe, adds a menu
engineering class (Star, Plowhorse, Puzzle, Dog).
Exit code: 0 ok, 1 errors in the data or HIGH findings, 2 usage or input error.
Standard library only.
"""
import json
import math
import re
import sys

UNITS = {  # unit -> (dimension, factor to base unit g / ml / each)
    "mg": ("mass", 0.001), "g": ("mass", 1.0), "kg": ("mass", 1000.0),
    "oz": ("mass", 28.3495), "lb": ("mass", 453.592),
    "ml": ("volume", 1.0), "cl": ("volume", 10.0), "dl": ("volume", 100.0), "l": ("volume", 1000.0),
    "each": ("count", 1.0), "pc": ("count", 1.0), "pcs": ("count", 1.0), "piece": ("count", 1.0),
    "pieces": ("count", 1.0), "unit": ("count", 1.0), "units": ("count", 1.0), "egg": ("count", 1.0), "eggs": ("count", 1.0),
}
BASE = {"mass": "g", "volume": "ml", "count": "each"}


def usage(msg):
    print(f"error: {msg}\n", file=sys.stderr)
    print(__doc__.strip().split("\n\n")[1], file=sys.stderr)
    sys.exit(2)


def parse_qty(text):
    """'600 g' -> (600.0, 'mass', 600.0 in base units)."""
    m = re.fullmatch(r"\s*(\d+(?:[.,]\d+)?)\s*([a-zA-Z]+)?\s*", str(text))
    if not m:
        raise ValueError(f"cannot read quantity {text!r}")
    qty = float(m.group(1).replace(",", "."))
    unit = (m.group(2) or "each").lower()
    if unit not in UNITS:
        raise ValueError(f"unknown unit {unit!r} in {text!r}")
    dim, factor = UNITS[unit]
    return qty, dim, qty * factor


def round_up(value, step):
    return math.ceil(round(value / step, 6)) * step


def analyze(data, target_override=None):
    errors, findings = [], []
    cur = data.get("currency", "")
    target = float(target_override or data.get("target_food_cost_pct", 30))
    tax = float(data.get("menu_price_includes_tax_pct", 0))
    step = float(data.get("price_rounding", 0.10))
    ingredients = {}
    for ing in data.get("ingredients", []):
        name = str(ing.get("name", "")).strip().lower()
        try:
            _, dim, base_qty = parse_qty(ing["per"])
            price = float(ing["price"])
        except (KeyError, ValueError, TypeError) as e:
            errors.append(f"ingredient {name or '?'}: {e}")
            continue
        y = float(ing.get("yield_pct", 100))
        if not 0 < y <= 100:
            errors.append(f"ingredient {name}: yield_pct must be between 1 and 100")
            continue
        ingredients[name] = {"dim": dim, "cost_per_base": price / base_qty / (y / 100), "yield": y, "used": False}

    results = []
    for rec in data.get("recipes", []):
        rname = rec.get("name", "?")
        portions = float(rec.get("portions", 1) or 1)
        lines, bad = [], False
        for item in rec.get("items", []):
            iname, qtext = str(item[0]).strip().lower(), item[1]
            ing = ingredients.get(iname)
            if not ing:
                errors.append(f"{rname}: unknown ingredient {iname!r} (add it to ingredients)")
                bad = True
                continue
            ing["used"] = True
            try:
                _, dim, base_qty = parse_qty(qtext)
            except ValueError as e:
                errors.append(f"{rname}: {e}")
                bad = True
                continue
            if dim != ing["dim"]:
                errors.append(f"{rname}: {iname} is bought by {BASE[ing['dim']]} but used by {BASE[dim]} ({qtext}); "
                              f"convert it (for example weigh one piece)")
                bad = True
                continue
            lines.append((iname, base_qty * ing["cost_per_base"]))
        if bad:
            continue
        batch = sum(c for _, c in lines)
        extras = float(rec.get("extras_per_portion", 0))
        cost = batch / portions + extras
        price = float(rec.get("menu_price", 0))
        net = price / (1 + tax / 100) if price else 0.0
        pct = 100 * cost / net if net else None
        suggested = round_up(cost / (target / 100) * (1 + tax / 100), step)
        drivers = sorted(lines, key=lambda x: -x[1])[:3]
        r = {"name": rname, "portions": portions, "cost_per_portion": round(cost, 3), "menu_price": price,
             "net_price": round(net, 2), "food_cost_pct": None if pct is None else round(pct, 1),
             "contribution_margin": round(net - cost, 2) if net else None,
             "suggested_price_at_target": round(suggested, 2), "sold_per_week": rec.get("sold_per_week"),
             "drivers": [{"ingredient": n, "share_pct": round(100 * c / batch, 1) if batch else 0} for n, c in drivers]}
        results.append(r)
        if pct is None:
            findings.append(("WARN", rname, f"no menu_price; suggested {cur} {suggested:.2f} at {target:g}% food cost"))
        elif pct > target + 15:
            findings.append(("HIGH", rname, f"food cost {pct:.1f}% is far above the {target:g}% target; "
                                            f"price {cur} {suggested:.2f} or cut cost {cost - net * target / 100:.2f} per portion"))
        elif pct > target + 5:
            findings.append(("WARN", rname, f"food cost {pct:.1f}% is above the {target:g}% target; "
                                            f"price at target would be {cur} {suggested:.2f}"))
        elif pct < target - 15:
            findings.append(("INFO", rname, f"food cost only {pct:.1f}%; check the recipe lists every ingredient and portion size"))
        if drivers and batch and drivers[0][1] / batch > 0.5:
            findings.append(("INFO", rname, f"{drivers[0][0]} is {100 * drivers[0][1] / batch:.0f}% of the cost; "
                                            f"its price or portion matters most"))

    sold = [r for r in results if isinstance(r["sold_per_week"], (int, float)) and r["contribution_margin"] is not None]
    if sold and len(sold) == len(results) and len(sold) >= 3:
        total = sum(r["sold_per_week"] for r in sold)
        pop_line = 0.7 / len(sold)
        avg_cm = sum(r["contribution_margin"] * r["sold_per_week"] for r in sold) / total if total else 0
        for r in sold:
            high_pop = total and r["sold_per_week"] / total >= pop_line
            high_cm = r["contribution_margin"] >= avg_cm
            r["menu_class"] = {(True, True): "Star", (True, False): "Plowhorse",
                               (False, True): "Puzzle", (False, False): "Dog"}[(bool(high_pop), high_cm)]
        findings.append(("INFO", None, f"menu engineering: weighted average margin {cur} {avg_cm:.2f}, "
                                       f"popularity line {100 * pop_line:.1f}% of items sold"))
    for name, ing in ingredients.items():
        if not ing["used"]:
            findings.append(("INFO", None, f"ingredient {name!r} is not used in any recipe"))
    return {"currency": cur, "target_pct": target, "tax_pct": tax, "recipes": results,
            "errors": errors, "findings": [{"severity": s, "recipe": n, "message": m} for s, n, m in findings]}


def main(argv):
    target, as_json, paths = None, False, []
    it = iter(argv)
    for a in it:
        if a == "--target":
            try:
                target = float(next(it, ""))
            except ValueError:
                usage("--target needs a number, for example 30")
            if not 5 <= target <= 80:
                usage("--target should be a food cost percent between 5 and 80")
        elif a == "--json":
            as_json = True
        elif a.startswith("--"):
            usage(f"unknown option {a}")
        else:
            paths.append(a)
    if len(paths) != 1:
        usage("give exactly one menu JSON file, or - for stdin")
    try:
        raw = sys.stdin.read() if paths[0] == "-" else open(paths[0], encoding="utf-8").read()
        data = json.loads(raw)
    except (OSError, ValueError) as e:
        print(f"error: cannot read menu JSON: {e}", file=sys.stderr)
        return 2
    if not data.get("recipes"):
        print("error: no recipes in the input", file=sys.stderr)
        return 2
    rep = analyze(data, target)
    if as_json:
        print(json.dumps(rep, indent=2))
    else:
        cur = rep["currency"]
        print(f"Target food cost {rep['target_pct']:g}% | prices include {rep['tax_pct']:g}% tax | currency {cur}\n")
        print(f"{'ITEM':<22} {'COST':>7} {'PRICE':>7} {'NET':>7} {'FOOD%':>6} {'MARGIN':>7} {'AT TARGET':>9}  CLASS")
        for r in rep["recipes"]:
            pct = "-" if r["food_cost_pct"] is None else f"{r['food_cost_pct']:.1f}"
            cm = "-" if r["contribution_margin"] is None else f"{r['contribution_margin']:.2f}"
            print(f"{r['name'][:22]:<22} {r['cost_per_portion']:>7.2f} {r['menu_price']:>7.2f} {r['net_price']:>7.2f} "
                  f"{pct:>6} {cm:>7} {r['suggested_price_at_target']:>9.2f}  {r.get('menu_class', '-')}")
        print("\nTop cost drivers:")
        for r in rep["recipes"]:
            print(f"  {r['name']}: " + ", ".join(f"{d['ingredient']} {d['share_pct']:g}%" for d in r["drivers"]))
        if rep["errors"]:
            print(f"\nErrors ({len(rep['errors'])}):")
            for e in rep["errors"]:
                print(f"  [ERROR] {e}")
        print(f"\nFindings ({len(rep['findings'])}):")
        order = {"HIGH": 0, "WARN": 1, "INFO": 2}
        for f in sorted(rep["findings"], key=lambda f: order[f["severity"]]):
            print(f"  [{f['severity']}] {f['recipe'] + ': ' if f['recipe'] else ''}{f['message']}")
    bad = rep["errors"] or any(f["severity"] == "HIGH" for f in rep["findings"])
    return 1 if bad else 0


if __name__ == "__main__":
sys.exit(main(sys.argv[1:]))Builds and reviews 5K to marathon running plans: a tested script checks weekly volume jumps, long run share and progression, hard and back-to-back days, rest and cutback weeks, peak timing, and taper, then the skill explains the risks in plain language and proposes a safer week-by-week plan.
---
name: running-plan-load-checker
description: Builds and reviews running training plans for 5K, 10K, half marathon, and marathon goals - checks weekly volume jumps, long run share and progression, hard days and back-to-back hard sessions, rest and cutback weeks, peak timing, and taper with a tested script, then explains the risks in plain language and proposes a safer week-by-week plan. Use when a runner shares a plan or asks "is this plan too much?", "build me a 12-week half marathon plan", or "how should I increase my mileage?".
---

# Running Plan Load Checker

You help everyday runners reach race day healthy. You build plans that progress gradually, and you review existing plans for the load mistakes that cause most overuse injuries: doing too much, too soon, with too little recovery.

You are a coach's assistant, not a doctor. Pain, illness, and medical conditions go to a professional (see `references/safety-and-red-flags.md`).

## Files in this skill

- `scripts/check_plan.py` - parses a plan table (Markdown or CSV) and checks load progression week by week (Python 3 standard library only)
- `references/training-principles.md` - progression, intensity balance, long runs, cutback weeks, peak and taper
- `references/safety-and-red-flags.md` - when to stop, see a professional, or adjust the plan
- `templates/training-plan.md` - the plan table format the script reads, plus the review layout
- `examples/example-half-marathon-review.md` - a draft plan reviewed and fixed

## Workflow

### 1. Get the runner's context
Ask for or confirm, in one short message:
- Goal race, distance, and date (or number of weeks available).
- Current running: weekly km over the last 4 weeks, runs per week, longest recent run.
- Experience level and injury history in the last year.
- Days available, and any day that must stay free.
- Goal: finish comfortably, or a time target.

If the runner has a health condition, is returning from injury, is pregnant, or is new to exercise, recommend checking with a doctor before following any plan.

### 2. Put the plan into the table format
Use `templates/training-plan.md`: one row per session with `week`, `day`, `type`, and `km`. Use type words the script knows (easy, recovery, long, tempo, intervals, hills, fartlek, race, cross, strength, rest).

### 3. Run the checker
```bash
python3 scripts/check_plan.py plan.md --race half --level intermediate --current-km 20
python3 scripts/check_plan.py plan.csv --race marathon --level beginner --current-km 30 --json
```
The weekly table shows km, runs, non-running days, long run, long run share, hard days, and the change versus the highest of the previous three weeks. Findings are HIGH (fix before using the plan) or WARN (review and justify). Exit code 1 means at least one HIGH finding.

If you cannot run the script, apply the same checks by hand using `references/training-principles.md` and say so.

### 4. Fix and explain
For each finding, change the plan rather than only describing the problem: smooth jumps, insert cutback weeks, move hard sessions apart, shift the peak, and shorten race week. Run the checker again until there are no HIGH findings, and keep any remaining WARN only with a reason (for example an experienced runner returning to a familiar volume).

### 5. Report
Use the review layout in `templates/training-plan.md`, as in `examples/example-half-marathon-review.md`: what changed and why, the final plan, how to adjust when life happens, and the safety notes.

## Rules
- Distances in km unless the runner uses miles; never mix units in one plan.
- Most running should feel easy (conversational). Describe intensity by effort and talk test, not only by pace.
- Do not prescribe diets, supplements, or medication.
- Never tell a runner to train through sharp, worsening, or limping pain.
- A missed week is normal: repeat the previous week instead of jumping ahead.
FILE:references/training-principles.md
# Training principles used by the checker

These are conservative rules of thumb for recreational runners. They are guidelines for spotting risk, not laws; experienced runners can justify exceptions.

## Weekly volume progression

- Compare each week with the **highest of the previous three weeks**, not only the week before, so returning to the volume you had before a cutback week is not penalized.
- Typical safe increase: up to about 10 percent for beginners, 12 percent for intermediate runners, 15 percent for advanced runners. The script warns above these and rates jumps above 25, 30, or 35 percent as HIGH.
- Small absolute changes (3 km or less) are ignored, because 10 percent of a 15 km week is too small to matter.
- Week 1 should start close to what the runner already does. Starting far above current volume is the most common plan mistake.

## Cutback weeks

- Every 3 to 4 weeks of building, reduce volume by about 20 to 30 percent for one week and shorten the long run.
- The script warns after five building weeks in a row without a drop of at least 15 percent (taper weeks excluded).

## Long runs

- The long run builds endurance, but it should not dominate the week. Share limits used: 50 percent of weekly km under 30 km per week, 45 percent under 60 km, 40 percent above. Race week is excluded.
- Increase the long run by about 1 to 3 km at a time. The script warns when it grows by more than 3 km and more than 20 percent over the previous best.
- Minimum longest run before race week: 6 km for 5K, 10 km for 10K, 16 km for a half marathon, 28 km for a marathon (beginner marathon plans often peak at 30 to 32 km).

## Intensity balance

- About 80 percent of running time easy, 20 percent moderate or hard.
- Hard sessions: tempo or threshold, intervals, hills, fartlek, progression runs, races. Maximum hard days per week used: beginner 1, intermediate 2, advanced 3.
- Do not put hard sessions or a hard session and the long run on consecutive days unless the runner is experienced and it is deliberate (the script warns).
- Strides (short relaxed accelerations) after an easy run count as easy.

## Rest

- Beginners and intermediates need at least one non-running day per week; two or three is normal for 3 to 4 run plans. Cross-training and strength work count as non-running days in the table.

## Peak and taper

- Half marathon and marathon: the biggest week should come 2 to 3 weeks before race week (the script flags a peak in the last two weeks as HIGH).
- Taper: reduce volume gradually over the last 1 to 3 weeks while keeping some short, sharp running. In race week, aim for about 40 to 60 percent of peak volume besides the race itself (the script warns above 60 percent).

## Units

- 1 mile = 1.609 km. Convert a whole plan before checking; the script reads only kilometers.
FILE:references/safety-and-red-flags.md
# Safety and red flags

Use this list whenever you build or review a plan. When in doubt, recommend that the runner sees a doctor, physiotherapist, or sports medicine professional. Do not diagnose.

## Stop running and get medical help right away
- Chest pain, pressure, or tightness; fainting or near fainting; unusual shortness of breath; a racing or irregular heartbeat.
- Signs of heat illness: confusion, stopping sweating, nausea or vomiting, a very high body temperature.

## Stop the session and rest, then get checked if it persists
- Pain that is sharp, localized to one spot on a bone, or makes you limp.
- Pain that gets worse as you run, or is worse the next morning.
- Swelling, numbness, or pain at night.
- Pain that lasts more than a few days of rest.

## Reduce or adjust the plan
- Feeling unusually tired for more than a few days, poor sleep, irritability, or a resting heart rate clearly higher than normal: take extra easy days.
- Mild illness above the neck (runny nose): easy running may be fine; illness below the neck (fever, chest congestion, stomach bug) or a fever: rest.
- Missed one week: repeat the last completed week. Missed two weeks or more: drop back two weeks of volume.
- Heat, altitude, and hills: run by effort, not pace, and shorten sessions on very hot days.

## Ask for a medical check before starting a plan
- New to exercise, returning after a long break, or over 40 and previously inactive.
- Known heart, lung, or metabolic conditions, or a family history of sudden cardiac problems.
- Pregnancy or recent childbirth.
- A recent injury, especially a bone stress injury.

## Fueling and hydration (general only)
- For runs longer than about 75 to 90 minutes, practice carrying water and some carbohydrate during training, not for the first time on race day.
- Specific nutrition, supplement, or weight advice belongs to a registered dietitian or doctor.

## How to say it
Be clear and kind: "That kind of pain is a reason to stop and get it checked before the next run. The plan will wait; we can adjust the weeks afterward."
FILE:templates/training-plan.md
# Training plan table (input for scripts/check_plan.py)

One row per session. Rest days can be listed with type `rest` and km `0`, or left out.

| week | day | type | km | notes |
|---|---|---|---|---|
| 1 | Tue | easy | 5 | conversational pace |
| 1 | Thu | tempo | 6 | 2x8 min comfortably hard, 2 min jog between |
| 1 | Sat | long | 10 | easy, practice drinking |
| 1 | Sun | cross | 0 | bike or swim 30 to 45 min, optional |

Columns:
- `week`: 1, 2, 3 ...
- `day`: Mon to Sun (or 1 to 7)
- `type`: easy, recovery, long, tempo, threshold, intervals, hills, fartlek, progression, race, cross, strength, rest
- `km`: distance in kilometers (0 for rest, cross, strength)
- `notes`: optional; the workout details

Run: `python3 scripts/check_plan.py plan.md --race <5k|10k|half|marathon> --level <beginner|intermediate|advanced> --current-km <km>`

---

# Plan review: <runner> - <race> on <date>

**Runner:** <current km/week, runs/week, longest recent run, level, injury history>
**Goal:** <finish / time target>   **Weeks:** <n>   **Days available:** <days>

## Checker result (before)
<HIGH and WARN findings, short>

## What I changed and why
1. <change> - fixes <finding>; <one-line reason>

## Final plan
<table in the format above>

## Checker result (after)
<"0 findings" or remaining WARN with the reason it is acceptable>

## How to adjust when life happens
- Missed a run: <rule>
- Missed a week: <rule>
- Feeling run down: <rule>

## Safety notes
- <relevant points from references/safety-and-red-flags.md>
FILE:examples/example-half-marathon-review.md
# Example: reviewing a 10-week half marathon draft

**Runner:** "I run about 20 km a week, 3 runs, longest run 9 km. I found this 10-week half marathon plan online. Is it OK?" Intermediate, no injuries in the last year, goal is to finish strong. Available Tue, Wed, Thu, Sat, Sun.

**Draft plan (summary):** weeks 1 to 9 build from 24 to 44 km with a long run growing 12 -> 20 km by 1 km per week, tempo or intervals every week (plus extra intervals in week 2 and hills in week 6), no cutback weeks, race on Sunday of week 10.

**Command:**
```bash
python3 scripts/check_plan.py draft.md --race half --level intermediate --current-km 20
```

**Output:**
```
WEEK     KM RUNS REST  LONG LONG% HARD  CHANGE
   1     24    3    4    12   50%    1       -
   2     31    4    3    13   42%    2    +29%
   3     28    3    4    14   50%    1    -10%
   4     34    4    3    15   44%    1    +10%
   5     37    4    3    16   43%    1     +9%
   6     39    4    3    17   44%    2     +5%
   7     40    4    3    18   45%    1     +3%
   8     42    4    3    19   45%    1     +5%
   9     44    4    3    20   45%    1     +5%
  10   40.1    4    3  21.1   53%    2     -9%

Findings: 6
  [HIGH] week 9: peak volume (44 km) falls in week 9, too close to race week 10; peak 2 to 3 weeks out
  [WARN] week 1: week 1 is 24 km versus current 20 km/week
  [WARN] week 2: volume 31 km is 29% above the recent max of 24 km (aim for 12% or less)
  [WARN] week 2: hard or long sessions on back-to-back days: 3-4
  [WARN] week 5: five weeks in a row without a cutback week (drop volume 20 to 30% every 3 to 4 weeks)
  [WARN] week 6: hard or long sessions on back-to-back days: 4-5, 5-6
```

---

# Plan review: half marathon in 12 weeks

**Runner:** 20 km/week, 3 runs, longest recent run 9 km, intermediate, no recent injuries
**Goal:** finish strong   **Weeks:** 12 (race moved to week 12 by starting two weeks earlier)   **Days available:** Tue, Wed, Thu, Sat, Sun

## Checker result (before)
1 HIGH (peak in the week before the race, so no taper) and 5 WARN (start too high, a 29 percent jump in week 2, back-to-back hard days in weeks 2 and 6, no cutback week).

## What I changed and why
1. Start at 21 km in week 1 - close to the current 20 km, so the body is not shocked in week 1.
2. Grow about 2 km per week (6 to 10 percent) - removes the week 2 jump.
3. Cutback weeks in weeks 4 and 8 (about 20 percent less, long run back to 10 km) - lets the body absorb the training.
4. One quality session per week on Thursday, never the day before or after the long run - fixes the back-to-back hard days.
5. Peak (36 km, long run 16 km) in week 10, then a taper week (26 km) and a light race week - the race is run fresh.
6. A fourth short easy run on Wednesday from week 2 - adds volume without making the long run heavier.

## Final plan

| week | km | Tue | Wed | Thu | Sat | Sun |
|---|---|---|---|---|---|---|
| 1 | 21 | easy 5 | - | easy 6 + strides | long 10 | - |
| 2 | 23 | easy 5 | easy 3 | tempo 5 (2x8 min) | long 10 | - |
| 3 | 25 | easy 6 | easy 3 | tempo 5 (2x10 min) | long 11 | - |
| 4 | 20 | easy 5 | - | easy 5 | long 10 | - |
| 5 | 27 | easy 6 | easy 4 | intervals 6 (5x1 km) | long 11 | - |
| 6 | 29 | easy 6 | easy 4 | tempo 7 (3x10 min) | long 12 | - |
| 7 | 31 | easy 6 | easy 5 | intervals 7 (6x1 km) | long 13 | - |
| 8 | 25 | easy 6 | easy 4 | easy 5 | long 10 | - |
| 9 | 34 | easy 7 | easy 5 | tempo 7 (2x15 min) | long 15 | - |
| 10 | 36 | easy 7 | easy 6 | intervals 7 (5x1.6 km) | long 16 | - |
| 11 | 26 | easy 6 | easy 4 | tempo 5 (20 min at goal pace) | long 11 | - |
| 12 | 30.1 | easy 5 + strides | - | easy 4 | - | RACE 21.1 |

Week 5 also has an optional 40-minute bike ride on Monday.

## Checker result (after)
`python3 scripts/check_plan.py revised.md --race half --level intermediate --current-km 20` -> `Findings: 0`, exit code 0.

## How to adjust when life happens
- Missed a run: skip it; do not squeeze it into the next day.
- Missed a week: repeat the last week you completed, then continue.
- Feeling run down or sore for more than two days: replace the quality session with an easy run or rest.

## Safety notes
- Stop and get checked for sharp, one-spot, or limping pain, or pain that is worse the next morning.
- Practice drinking (and a small carbohydrate snack) on long runs from week 9, so race day holds no surprises.
FILE:scripts/check_plan.py
#!/usr/bin/env python3
"""Check a running training plan for risky load jumps and missing structure.

Usage:
  python3 check_plan.py plan.md [--race 5k|10k|half|marathon] [--level beginner|intermediate|advanced]
                        [--current-km 20] [--json]
  python3 check_plan.py plan.csv ...
  cat plan.md | python3 check_plan.py - ...

The plan is a Markdown table or CSV with a header row containing at least
week, day, type and km (also accepted: distance, dist). Optional columns are
ignored. One row per session; rest days may be listed or left out.
  day:  Mon..Sun, Monday..Sunday or 1..7
  type: easy, recovery, long, tempo, threshold, intervals, hills, fartlek,
        progression, race, cross, strength, rest  (anything else counts as easy)
  km:   number (use 0 for rest, cross and strength)

Checks per week: volume increase versus the highest of the previous three
weeks, long run share of the week (limit 50% under 30 km, 45% under 60 km,
40% above; race week excluded), long run jumps, number of hard days,
hard or long sessions on back-to-back days, rest days, and cutback weeks.
Plan-level checks: first week versus current weekly volume, longest run
versus the race distance, peak week too close to race day, and taper.
Exit code: 0 no HIGH findings, 1 at least one HIGH finding, 2 usage or input error.
Standard library only.
"""
import csv
import io
import json
import re
import sys

DAYS = {"mon": 1, "tue": 2, "wed": 3, "thu": 4, "fri": 5, "sat": 6, "sun": 7}
HARD = {"tempo", "threshold", "intervals", "interval", "hills", "hill", "fartlek", "progression", "race", "speed", "track"}
NON_RUN = {"rest", "cross", "strength", "off", "yoga", "bike", "swim"}
RACE_KM = {"5k": 5.0, "10k": 10.0, "half": 21.1, "marathon": 42.2}
MIN_LONG = {"5k": 6, "10k": 10, "half": 16, "marathon": 28}
LIMITS = {  # weekly increase warn, weekly increase high, max hard days
    "beginner": (0.10, 0.25, 1),
    "intermediate": (0.12, 0.30, 2),
    "advanced": (0.15, 0.35, 3),
}


def long_share_limit(week_km):
    """Low-volume weeks naturally have a bigger long-run share."""
    return 0.50 if week_km < 30 else 0.45 if week_km < 60 else 0.40


def usage(msg):
    print(f"error: {msg}\n", file=sys.stderr)
    print(__doc__.strip().split("\n\n")[1], file=sys.stderr)
    sys.exit(2)


def read_rows(text):
    lines = [ln for ln in text.splitlines() if ln.strip()]
    if not lines:
        return []
    if lines[0].lstrip().startswith("|") or sum(ln.count("|") >= 3 for ln in lines) > len(lines) / 2:
        rows = []
        for ln in lines:
            if "|" not in ln or re.match(r"^\s*\|?\s*:?-{2,}", ln):
                continue
            rows.append([c.strip() for c in ln.strip().strip("|").split("|")])
    else:
        rows = list(csv.reader(io.StringIO("\n".join(lines))))
    header = [h.strip().lower() for h in rows[0]]
    out = []
    for r in rows[1:]:
        out.append({header[i]: (r[i].strip() if i < len(r) else "") for i in range(len(header))})
    return out


def num(value):
    m = re.search(r"\d+(?:[.,]\d+)?", value or "")
    return float(m.group(0).replace(",", ".")) if m else 0.0


def parse(rows):
    if not rows:
        raise ValueError("no table rows found")
    keys = rows[0].keys()
    kcol = next((k for k in ("km", "distance", "dist", "distance_km") if k in keys), None)
    for need, col in (("week", "week" in keys), ("day", "day" in keys), ("type", "type" in keys), ("km", kcol)):
        if not col:
            raise ValueError(f"missing column '{need}' (found: {', '.join(keys)})")
    sessions = []
    for i, r in enumerate(rows, 2):
        w = num(r["week"])
        d = r["day"].strip().lower()
        day = DAYS.get(d[:3]) if d[:3] in DAYS else (int(d) if d.isdigit() and 1 <= int(d) <= 7 else None)
        if not w or day is None:
            raise ValueError(f"row {i}: cannot read week/day from {r['week']!r}/{r['day']!r}")
        t = (r["type"].strip().lower().split() or ["easy"])[0]
        km = num(r[kcol])
        sessions.append({"week": int(w), "day": day, "type": t, "km": 0.0 if t in NON_RUN else km})
    return sessions


def analyze(sessions, race, level, current_km):
    warn_up, high_up, max_hard = LIMITS[level]
    weeks = {}
    for s in sessions:
        weeks.setdefault(s["week"], []).append(s)
    findings, table = [], []

    def add(sev, week, msg):
        findings.append({"severity": sev, "week": week, "message": msg})

    prev_long = []
    week_nums = sorted(weeks)
    for idx, w in enumerate(week_nums):
        ss = sorted(weeks[w], key=lambda s: s["day"])
        runs = [s for s in ss if s["km"] > 0]
        total = round(sum(s["km"] for s in runs), 1)
        run_days = sorted({s["day"] for s in runs})
        longest = max((s["km"] for s in runs), default=0.0)
        hard_days = sorted({s["day"] for s in runs if s["type"] in HARD})
        stress_days = sorted({s["day"] for s in runs if s["type"] in HARD or s["type"] == "long"})
        ref = max((r["km"] for r in table[-3:]), default=None)
        change = None if not ref else (total - ref) / ref
        row = {"week": w, "km": total, "runs": len(runs), "rest_days": 7 - len(run_days), "long_km": longest,
               "long_share": round(longest / total, 2) if total else 0.0, "hard_days": len(hard_days),
               "change_vs_recent_max": None if change is None else round(change * 100)}
        table.append(row)
        if change is not None and total - ref > 3:
            if change > high_up:
                add("HIGH", w, f"volume {total:g} km is {change:.0%} above the recent max of {ref:g} km (limit {high_up:.0%})")
            elif change > warn_up:
                add("WARN", w, f"volume {total:g} km is {change:.0%} above the recent max of {ref:g} km (aim for {warn_up:.0%} or less)")
        is_race_week = bool(race) and idx == len(week_nums) - 1
        long_share = long_share_limit(total)
        share = round(longest / total, 2) if total else 0.0
        if total >= 15 and not is_race_week and share > long_share:
            sev = "HIGH" if share > long_share + 0.15 else "WARN"
            add(sev, w, f"long run {longest:g} km is {share:.0%} of the week's {total:g} km (aim for {long_share:.0%} or less)")
        if prev_long and longest > max(prev_long) + 3 and longest > max(prev_long) * 1.2 and not is_race_week:
            add("WARN", w, f"longest run jumps to {longest:g} km from a previous best of {max(prev_long):g} km (add 1 to 3 km at a time)")
        prev_long.append(longest)
        if len(hard_days) > max_hard:
            add("WARN", w, f"{len(hard_days)} hard days (days {', '.join(map(str, hard_days))}); {level} plans usually have at most {max_hard}")
        b2b = [(a, b) for a, b in zip(stress_days, stress_days[1:]) if b - a == 1]
        if b2b:
            add("WARN", w, "hard or long sessions on back-to-back days: " + ", ".join(f"{a}-{b}" for a, b in b2b))
        if len(run_days) == 7 and level != "advanced":
            add("WARN", w, "no rest day this week")

    # cutback weeks: in any 5 consecutive weeks of build-up, expect one week at least 15% below the week before
    build = [r for r in table]
    if race and len(build) >= 3:
        build = build[:-2]  # leave the taper out
    streak = 0
    for i, r in enumerate(build):
        if i and build[i - 1]["km"] and r["km"] <= build[i - 1]["km"] * 0.85:
            streak = 0
        else:
            streak += 1
        if streak == 5:
            add("WARN", r["week"], "five weeks in a row without a cutback week (drop volume 20 to 30% every 3 to 4 weeks)")
            streak = 0

    if current_km is not None and table:
        first = table[0]["km"]
        if current_km == 0 and first > 10:
            add("HIGH", table[0]["week"], f"week 1 starts at {first:g} km from no running; begin with run-walk sessions")
        elif current_km and (first - current_km) / current_km > high_up and first - current_km > 3:
            add("HIGH", table[0]["week"], f"week 1 is {first:g} km but current volume is {current_km:g} km/week ({(first - current_km) / current_km:.0%} jump)")
        elif current_km and (first - current_km) / current_km > warn_up and first - current_km > 3:
            add("WARN", table[0]["week"], f"week 1 is {first:g} km versus current {current_km:g} km/week")

    if race and table:
        peak = max(table, key=lambda r: r["km"])
        last = table[-1]["week"]
        race_rows = [s for s in sessions if s["type"] == "race"]
        if not race_rows:
            add("INFO", last, "no session with type 'race'; the last week is treated as race week")
        build_long = max((r["long_km"] for r in table[:-1]), default=0)
        if build_long < MIN_LONG[race]:
            add("HIGH" if race in ("half", "marathon") else "WARN", None,
                f"longest training run before race week is {build_long:g} km; for a {race} aim for at least {MIN_LONG[race]} km")
        if len(table) >= 3 and race in ("half", "marathon") and peak["week"] >= last - 1:
            add("HIGH", peak["week"], f"peak volume ({peak['km']:g} km) falls in week {peak['week']}, too close to race week {last}; peak 2 to 3 weeks out")
        if len(table) >= 2:
            race_km = sum(s["km"] for s in sessions if s["type"] == "race")
            race_week_other = table[-1]["km"] - race_km
            if peak["km"] and race_week_other > 0.6 * peak["km"]:
                add("WARN", last, f"race week has {race_week_other:g} km besides the race ({race_week_other / peak['km']:.0%} of peak); taper to about 40 to 60%")
    return table, findings


def main(argv):
    opts = {"race": None, "level": "intermediate", "current": None, "json": False}
    paths = []
    it = iter(argv)
    for a in it:
        if a == "--race":
            opts["race"] = (next(it, "") or "").lower()
            if opts["race"] not in RACE_KM:
                usage("--race must be 5k, 10k, half or marathon")
        elif a == "--level":
            opts["level"] = (next(it, "") or "").lower()
            if opts["level"] not in LIMITS:
                usage("--level must be beginner, intermediate or advanced")
        elif a == "--current-km":
            v = next(it, "")
            try:
                opts["current"] = float(v)
            except ValueError:
                usage("--current-km needs a number")
        elif a == "--json":
            opts["json"] = True
        elif a.startswith("--"):
            usage(f"unknown option {a}")
        else:
            paths.append(a)
    if len(paths) != 1:
        usage("give exactly one plan file, or - for stdin")
    try:
        text = sys.stdin.read() if paths[0] == "-" else open(paths[0], encoding="utf-8").read()
        sessions = parse(read_rows(text))
    except (OSError, ValueError) as e:
        print(f"error: {e}", file=sys.stderr)
        return 2
    table, findings = analyze(sessions, opts["race"], opts["level"], opts["current"])
    order = {"HIGH": 0, "WARN": 1, "INFO": 2}
    findings.sort(key=lambda f: (order[f["severity"]], f["week"] or 0))
    if opts["json"]:
        print(json.dumps({"weeks": table, "findings": findings}, indent=2))
    else:
        print(f"Plan: {len(table)} weeks, {sum(r['km'] for r in table):g} km total | level={opts['level']}"
              f" race={opts['race'] or '-'} current={opts['current'] if opts['current'] is not None else '-'} km/week")
        print(f"\n{'WEEK':>4} {'KM':>6} {'RUNS':>4} {'REST':>4} {'LONG':>5} {'LONG%':>5} {'HARD':>4} {'CHANGE':>7}")
        for r in table:
            ch = "-" if r["change_vs_recent_max"] is None else f"{r['change_vs_recent_max']:+d}%"
            print(f"{r['week']:>4} {r['km']:>6g} {r['runs']:>4} {r['rest_days']:>4} {r['long_km']:>5g} "
                  f"{r['long_share']:>5.0%} {r['hard_days']:>4} {ch:>7}")
        print(f"\nFindings: {len(findings)}")
        for f in findings:
            where = f"week {f['week']}" if f["week"] else "plan"
            print(f"  [{f['severity']}] {where}: {f['message']}")
        if not findings:
            print("  none - load progression looks reasonable")
    return 1 if any(f["severity"] == "HIGH" for f in findings) else 0


if __name__ == "__main__":
sys.exit(main(sys.argv[1:]))Turns noisy application, server, and access logs into a ranked list of error patterns with counts, first and last seen, spikes, and patterns that are new versus a known-good baseline, then separates root causes from symptoms and writes a short incident triage report. Includes a tested stdlib Python log clusterer.
---
name: log-error-pattern-triage
description: Triages large or noisy application, server, and access logs - groups thousands of lines into a ranked list of error patterns with counts, first and last seen, spikes, and patterns that are new compared with a known-good baseline, then separates root causes from downstream symptoms and writes a short incident triage report with next checks. Use when a user pastes or uploads logs, asks "what is going wrong in these logs?", "why did errors spike at 10:09?", or needs a first-pass incident summary.
---

# Log Error Pattern Triage

You turn a wall of log lines into a short, ranked list of problems and a clear next step. You never paste the whole log back; you count, group, compare, and explain.

## Files in this skill

- `scripts/cluster_logs.py` - groups log entries into masked patterns, ranks them, detects spikes, and marks patterns that are NEW versus a baseline log (Python 3 standard library only)
- `references/log-normalization.md` - how lines become patterns, what is masked, and how to handle formats the script does not know
- `references/triage-heuristics.md` - how to rank patterns, tell root causes from symptoms, and decide what to check next
- `templates/triage-report.md` - the report format
- `examples/example-checkout-incident.md` - a worked triage of a payment timeout spike

## Workflow

### 1. Get the right slice of logs
Ask for (or confirm) the service name, the time window around the problem with the time zone, and if possible a log from a known-good period of the same length to use as a baseline. If the log is huge, work on the window that matters; a 15-minute slice around the incident is usually enough.

Remove secrets before sharing: tokens, passwords, session cookies, and personal data. If you see any in the input, say so and do not repeat them.

### 2. Run the clusterer
```bash
python3 scripts/cluster_logs.py app.log
python3 scripts/cluster_logs.py app.log --baseline yesterday.log --top 20
python3 scripts/cluster_logs.py access.log --min-level INFO
kubectl logs deploy/api --since=30m | python3 scripts/cluster_logs.py - --json
```
It prints one row per pattern with level, count, share, first and last seen, and flags (`NEW` = not in the baseline, `SPIKE` = a minute with at least 3 times the usual rate), followed by a real sample line and the last stack trace line for each pattern. Exit code 1 means at least one ERROR or FATAL pattern was found.

If you cannot run the script, group lines by hand using the masking rules in `references/log-normalization.md` and say that counts are approximate.

### 3. Triage
Apply `references/triage-heuristics.md`:
1. Order the patterns by impact: FATAL and NEW+SPIKE first, then by count, then by user-facing effect.
2. Build a short timeline from first-seen times. The earliest new pattern in a burst is usually closer to the cause; patterns that start seconds later are often symptoms.
3. Separate root cause candidates, symptoms, and background noise that also exists in the baseline.
4. For every root cause candidate, name the evidence and the cheapest next check (a dashboard, a dependency status page, a config diff, a deploy log, a specific query).

### 4. Report
Fill in `templates/triage-report.md`, as in `examples/example-checkout-incident.md`. Keep the summary to three sentences a manager can read.

## Rules
- Quote real sample lines; never invent log lines, counts, or times.
- State the time zone of the log and keep it consistent.
- Do not claim a root cause from logs alone; say "most likely" and list what would confirm it.
- Treat noise honestly: if a pattern is also in the baseline at a similar rate, it is not the incident.
- Never suggest deleting logs or turning off logging to make errors go away.
FILE:references/log-normalization.md
# Log normalization: from lines to patterns

Grouping works by turning every message into a template: the fixed words stay, the variable parts become placeholders. Two lines with the same template are the same problem happening more than once.

## What the script masks

| Variable part | Example | Placeholder |
| --- | --- | --- |
| UUID | `0288ddd8-5e8c-45f9-a0e7-486d8fa66b03` | `<uuid>` |
| Email address | `li@example.com` | `<email>` |
| IPv4 address with optional port | `192.0.2.44:5432` | `<ip>` |
| Hex values and long hex ids | `0x7f3a`, `9f1c2e7a4b3d` | `<hex>` |
| URL query string | `?page=2&sort=price` | `?<query>` |
| Quoted values | `'cart:42'`, `"Bob"` | `<str>` |
| Numbers with optional unit | `5000ms`, `89%`, `17` | `<n>` |
| Bracketed ids that contain a digit | `[http-nio-8080-exec-9]`, `[req-ab12]` | `[<id>]` |

Timestamps and levels are parsed first and removed from the message. For syslog lines the hostname is dropped so the same problem on `web-01` and `web-02` groups together. For access logs the template is `METHOD /path -> HTTPstatus`, with numeric path segments masked, so `/api/orders/123` and `/api/orders/456` group.

## Formats understood

- Plain lines with ISO-8601 timestamps: `2026-10-09T10:09:00.123Z ERROR [thread] logger - message`
- Syslog: `Oct  9 03:12:44 web-02 kernel: message`
- Nginx and Apache combined access logs: `... [09/Oct/2026:09:58:02 +0300] "POST /api/checkout HTTP/1.1" 502 ...`
- JSON lines with `level` or `severity`, `msg` or `message`, `time` or `timestamp`, and optional `error`

## Multi-line entries

Stack traces belong to the line above them. The script attaches indented lines, `Traceback (most recent call last)`, `Caused by:`, Java `at ...(File.java:12)` frames, `... 12 more`, and bare exception lines such as `java.net.SocketTimeoutException: Read timed out`. The last attached line is shown as "trace ends" because it often names the deepest frame or the real exception.

## Levels

Explicit levels win (`TRACE/DEBUG`, `INFO/NOTICE`, `WARN/WARNING`, `ERROR/ERR/SEVERE`, `CRITICAL/FATAL/PANIC`). A line without a level is rated by its wording: failure words (failed, out of memory, timed out, refused, denied, killed) count as ERROR and retry or deprecation words as WARN. Access log status 5xx is ERROR, 4xx other than 404 is WARN.

## When grouping goes wrong

- **Too many tiny patterns**: a variable word is not masked (usernames, hostnames inside the message, file names). Mention it, and group those rows yourself in the report, for example "2 patterns: SSH brute force from 2 IPs with different usernames".
- **One giant pattern hides two problems**: the message is generic ("request failed"). Look at the samples and trace tails, or rerun on a narrower time window.
- **Unknown format**: if most entries show no timestamp, convert the log first (for example with `jq -c` for nested JSON) or describe the format and group by hand.
- **Truncated lines**: templates are cut at 160 characters; samples at 200.
FILE:references/triage-heuristics.md
# Triage heuristics

## Rank patterns by impact, not by volume

1. **FATAL or crash patterns** (process exit, out of memory, panic): even one matters.
2. **NEW and SPIKE together**: something changed. This is usually the incident.
3. **User-facing errors** (5xx on customer endpoints, failed checkouts, failed logins) over internal ones (cache misses, retries that later succeed).
4. **Count and share**: within the same tier, bigger first.
5. **Baseline noise last**: patterns present in the baseline at a similar rate are background, not the incident.

## Root cause or symptom?

| Clue | Leans root cause | Leans symptom |
| --- | --- | --- |
| Timing | first new pattern in the burst | starts seconds after another pattern |
| Location | names a dependency, config, resource limit, or deploy | generic wrapper ("request failed", "checkout failed") |
| Stack trace | deepest frame is in a client library or resource call | trace ends in your own controller code that called something else |
| Ratio | count matches the number of failed upstream calls | count equals the sum of several other patterns |
| Baseline | absent before | present before at a lower rate |

A common chain: dependency timeout (cause) -> request handler fails (symptom) -> retries raise load (amplifier) -> connection pool saturates (secondary symptom).

## Typical causes behind common patterns

- **Timeouts to one dependency**: dependency outage or slowness, network change, too-low timeout after a deploy, connection pool exhaustion on the caller.
- **Connection pool near or at 100 percent**: slow queries or slow downstream calls holding connections, a leak, or traffic growth.
- **Out of memory and killed processes**: oversized input, memory leak, container limit lowered, too many workers per host.
- **Permission denied / read-only file system**: deploy changed the user or volume mount, disk full, secrets rotated.
- **429 or throttling**: a client or job hammering an endpoint, or your own retry storm.
- **SMTP or email failures**: usually the provider's rate limit or outage; rarely the incident unless emails are the product.

## Cheapest next checks

- Deploys and config changes in the 30 minutes before the first new pattern.
- The dependency's status page and its latency and error dashboards.
- Host metrics at the spike minute: CPU, memory, disk, open connections.
- One full sample request traced end to end (trace id or request id).
- Whether the pattern stopped on its own, and what changed at that minute.

## Words to use in reports

- "Most likely cause" when logs plus timing point one way but nothing confirms it yet.
- "Confirmed" only with independent evidence (provider incident, rollback fixed it, metric proof).
- Give numbers: "30 payment timeouts in 2 minutes, 0 in the baseline".
FILE:templates/triage-report.md
# Log Triage Report: <service> <date>

**Window:** <start> to <end> (<time zone>) | **Entries read:** <n> | **At WARN or above:** <n> in <n> patterns
**Baseline:** <file and window, or "none">

## Summary (3 sentences)
<What broke, for whom, since when, and the most likely cause, in plain words.>

## Ranked patterns

| # | Level | Count | Flags | Pattern (short) | Role |
| --- | --- | --- | --- | --- | --- |
| 1 | ERROR | <n> | NEW, SPIKE | <pattern> | root cause candidate / symptom / noise |

## Timeline
- <hh:mm:ss> <first new pattern>
- <hh:mm:ss> <next event>
- <hh:mm:ss> <recovery, or "still ongoing at end of log">

## Root cause candidates
1. **<candidate>** - evidence: <sample line, counts, timing>. Confidence: <low/medium/high>.
   Next check: <one concrete check>.

## Symptoms and side effects
- <pattern> is caused by <candidate> because <reason>.

## Background noise (also in baseline)
- <pattern> at <rate> per minute, same as baseline.

## Recommended next steps
1. <immediate mitigation, if any>
2. <check that confirms or rules out the main candidate>
3. <follow-up: alert, timeout, retry, or logging improvement>

## Gaps
- <missing logs, unknown time zone, lines that could not be parsed>
FILE:examples/example-checkout-incident.md
# Example: checkout payment timeout spike

**User:** Checkout errors jumped around 10:09 this morning (UTC). Here is a 15-minute slice of the API log and yesterday's log for the same window. What happened?

**Command:**
```bash
python3 scripts/cluster_logs.py app.log --baseline baseline.log
```

**Script output (abridged):**
```
Read 138 entries (0 without a timestamp); 60 at WARN or above in 5 patterns.
Time range: 10-09 10:00:00 -> 10-09 10:14:48

 #  LEVEL COUNT  SHARE  FIRST          LAST           FLAGS      TEMPLATE
 1  ERROR    30  50.0%  10-09 10:09:00 10-09 10:10:56 NEW,SPIKE  [<id>] c.s.payments.PaymentClient - payment authorization timed out after <n> for order <n> (provider=psp-eu, attempt=<n>)
 2  ERROR    10  16.7%  10-09 10:09:00 10-09 10:10:48 NEW,SPIKE  [<id>] c.s.checkout.OrderController - checkout failed for session <uuid>
 3  ERROR     3   5.0%  10-09 10:03:30 10-09 10:12:30 -          [<id>] c.s.mail.ReceiptMailer - failed to send receipt to <email>: SMTP <n> try again later
 4  WARN     14  23.3%  10-09 10:00:42 10-09 10:14:42 -          [<id>] c.s.cache.RedisCache - cache miss for key <str> took <n>
 5  WARN      3   5.0%  10-09 10:02:45 10-09 10:11:45 -          [<id>] c.s.db.Hikari - connection pool at <n> (<n>/<n> active)

Details:
 2. ... trace ends: at com.shop.checkout.OrderController.submit(OrderController.java:77)
    spike: 5/min at 10:09 (median 0/min)
```

---

# Log Triage Report: checkout API 2026-10-09

**Window:** 10:00:00 to 10:14:48 (UTC) | **Entries read:** 138 | **At WARN or above:** 60 in 5 patterns
**Baseline:** baseline.log, 2026-10-08 10:00 to 10:10 UTC

## Summary (3 sentences)
From 10:09:00 to about 10:11 UTC, card payments timed out at the payment provider psp-eu and customers saw failed checkouts. The payment timeouts are new compared with yesterday and peaked at 15 per minute, and every failed checkout carries a socket read timeout from the payment client. The most likely cause is slowness or an outage at psp-eu; nothing in this log points to our own code or database.

## Ranked patterns

| # | Level | Count | Flags | Pattern (short) | Role |
| --- | --- | --- | --- | --- | --- |
| 1 | ERROR | 30 | NEW, SPIKE | payment authorization timed out after 5000ms (provider=psp-eu) | root cause candidate |
| 2 | ERROR | 10 | NEW, SPIKE | checkout failed for session ... (SocketTimeoutException) | symptom of 1 |
| 3 | ERROR | 3 | - | failed to send receipt ... SMTP 421 | noise (also in baseline) |
| 4 | WARN | 14 | - | cache miss for key 'cart:...' | noise (also in baseline) |
| 5 | WARN | 3 | - | connection pool at 85 to 97 percent | watch (also in baseline) |

## Timeline
- 10:09:00 first payment authorization timeout and first failed checkout, in the same second
- 10:09 peak minute: 15 timeouts per minute
- 10:10:56 last payment timeout; no further payment errors until the end of the log at 10:14:48

## Root cause candidates
1. **Payment provider psp-eu slow or unavailable** - evidence: 30 timeouts after exactly 5000 ms, all for provider=psp-eu, none in the baseline; stack traces end in `PaymentClient.authorize`. Confidence: medium.
   Next check: psp-eu status page and our outbound latency dashboard for 10:08 to 10:12 UTC.

## Symptoms and side effects
- "checkout failed for session" is caused by candidate 1: same start second, and its trace ends in `PaymentClient.authorize` via `OrderController.submit`.
- Retries (attempt=2 and 3 in the samples) may have added load during the spike.

## Background noise (also in baseline)
- SMTP 421 receipt failures (3 in 15 minutes) and cache misses appear yesterday at a similar rate.
- Connection pool warnings at 85 to 97 percent also appear yesterday; not the incident, but close to the limit.

## Recommended next steps
1. Confirm with the provider status page; if confirmed, no rollback is needed.
2. Count orders that failed between 10:09 and 10:11 and decide whether to email those customers.
3. Follow-up: alert on payment timeouts above 5 per minute, cap retries with backoff, and look at the connection pool headroom.

## Gaps
- No provider-side logs or metrics; the 5000 ms timeout hides how slow the provider really was.
FILE:scripts/cluster_logs.py
#!/usr/bin/env python3
"""Group log lines into error patterns (templates) and rank them for triage.

Usage:
  python3 cluster_logs.py app.log [more.log ...] [options]
  cat app.log | python3 cluster_logs.py - [options]

Options:
  --min-level LEVEL   lowest level to include: DEBUG, INFO, WARN, ERROR (default WARN)
  --top N             show the N largest patterns (default 15)
  --baseline FILE     log from a known-good period; patterns not seen there are marked NEW
  --json              print machine-readable JSON instead of a table

Understands plain lines with an ISO-8601, syslog ("Oct 09 10:01:02") or
nginx ("[09/Oct/2026:10:01:02 +0300]") timestamp, and JSON lines with
level/msg/message/time/timestamp keys, and web server access logs (method,
path and status are kept; 5xx counts as ERROR, 4xx other than 404 as WARN).
Indented lines, "Traceback", "at ...", "Caused by" and bare
"pkg.SomeException: ..." lines are attached to the entry above them.
Lines without an explicit level are rated by wording ("failed", "out of
memory", "timed out" -> ERROR; "retrying", "deprecated" -> WARN).
Variable parts (UUIDs, hex ids, IPs, emails, numbers, quoted values, URL
query strings) are masked so repeats of the same problem group together.
Exit code: 0 no ERROR-level patterns, 1 ERROR or worse found, 2 usage/input error.
Standard library only.
"""
import json
import re
import statistics
import sys
from collections import OrderedDict
from datetime import datetime

LEVELS = {"TRACE": 0, "DEBUG": 0, "INFO": 1, "NOTICE": 1, "WARN": 2, "WARNING": 2,
          "ERROR": 3, "ERR": 3, "SEVERE": 3, "CRITICAL": 4, "CRIT": 4, "FATAL": 4, "PANIC": 4, "ALERT": 4, "EMERG": 4}
CANON = {0: "DEBUG", 1: "INFO", 2: "WARN", 3: "ERROR", 4: "FATAL"}
MONTHS = {m: i for i, m in enumerate(["Jan", "Feb", "Mar", "Apr", "May", "Jun", "Jul", "Aug", "Sep", "Oct", "Nov", "Dec"], 1)}

TS_ISO = re.compile(r"(\d{4}-\d{2}-\d{2})[T ](\d{2}:\d{2}:\d{2})(?:[.,]\d+)?(?:Z|[+-]\d{2}:?\d{2})?")
TS_SYSLOG = re.compile(r"\b(Jan|Feb|Mar|Apr|May|Jun|Jul|Aug|Sep|Oct|Nov|Dec)\s+(\d{1,2}) (\d{2}:\d{2}:\d{2})")
TS_NGINX = re.compile(r"\[(\d{2})/(\w{3})/(\d{4}):(\d{2}:\d{2}:\d{2})[^\]]*\]")
LEVEL_RE = re.compile(r"(?<![\w-])(TRACE|DEBUG|INFO|NOTICE|WARNING|WARN|ERROR|ERR|SEVERE|CRITICAL|CRIT|FATAL|PANIC)(?![\w-])", re.I)
ERROR_HINT = re.compile(r"\b(out of memory|oom-?kill\w*|killed process|segfault|panic|fatal|failed|failure|"
                        r"exception|refused|timed out|timeout|denied|unreachable|code=killed)\b", re.I)
WARN_HINT = re.compile(r"\b(deprecated|retrying|retry|slow|degraded|throttl\w*)\b", re.I)
ACCESS_RE = re.compile(r'"(GET|POST|PUT|PATCH|DELETE|HEAD|OPTIONS) (\S+) HTTP/[\d.]+" (\d{3}) ')
CONT_RE = re.compile(r"^(\s+\S|Traceback \(most recent call last\)|Caused by:|\s*at [\w$.<>]+\(|\s*\.\.\. \d+ more|[\w$]+(?:\.[\w$]+)+(?:Exception|Error)(?::|$))")

MASKS = [
    (re.compile(r"\b[0-9a-f]{8}-[0-9a-f]{4}-[0-9a-f]{4}-[0-9a-f]{4}-[0-9a-f]{12}\b", re.I), "<uuid>"),
    (re.compile(r"\b[\w.+-]+@[\w-]+\.[\w.-]+\b"), "<email>"),
    (re.compile(r"\b\d{1,3}(?:\.\d{1,3}){3}(?::\d+)?\b"), "<ip>"),
    (re.compile(r"\b0x[0-9a-f]+\b", re.I), "<hex>"),
    (re.compile(r"\b(?=[0-9a-f]*\d)(?=[0-9a-f]*[a-f])[0-9a-f]{12,}\b", re.I), "<hex>"),
    (re.compile(r"\?[^\s\"']+"), "?<query>"),
    (re.compile(r"\"[^\"]{0,200}\"|'[^']{0,200}'"), "<str>"),
    (re.compile(r"(?<![\w<])[-+]?\d+(?:\.\d+)?(?:ms|s|kb|mb|gb|%)?(?![\w>])", re.I), "<n>"),
]


def usage(msg):
    print(f"error: {msg}\n", file=sys.stderr)
    print(__doc__.strip().split("\n\n")[1], file=sys.stderr)
    sys.exit(2)


def parse_time(line):
    m = TS_ISO.search(line)
    if m:
        return datetime.strptime(f"{m.group(1)} {m.group(2)}", "%Y-%m-%d %H:%M:%S"), m.span()
    m = TS_NGINX.search(line)
    if m and m.group(2) in MONTHS:
        d = datetime(int(m.group(3)), MONTHS[m.group(2)], int(m.group(1)))
        h, mi, s = map(int, m.group(4).split(":"))
        return d.replace(hour=h, minute=mi, second=s), m.span()
    m = TS_SYSLOG.search(line)
    if m:
        h, mi, s = map(int, m.group(3).split(":"))
        return datetime(1900, MONTHS[m.group(1)], int(m.group(2)), h, mi, s), m.span()
    return None, None


def parse_line(line):
    """Return (time, level_num, message) for the first line of an entry."""
    s = line.strip()
    if s.startswith("{"):
        try:
            obj = json.loads(s)
        except ValueError:
            obj = None
        if isinstance(obj, dict):
            lvl = str(obj.get("level") or obj.get("severity") or obj.get("lvl") or "INFO").upper()
            msg = str(obj.get("msg") or obj.get("message") or obj.get("error") or s)
            if obj.get("error") and obj.get("error") != msg:
                msg += f" error={obj['error']}"
            ts = str(obj.get("time") or obj.get("timestamp") or obj.get("ts") or "")
            t, _ = parse_time(ts)
            return t, LEVELS.get(lvl, 1), msg
    t, span = parse_time(s)
    rest = s[span[1]:] if span else s
    acc = ACCESS_RE.search(rest)
    if acc:  # web server access log: keep method, path and status, level from status
        method, path, status = acc.group(1), acc.group(2).split("?")[0], acc.group(3)
        lvl = 3 if status.startswith("5") else 2 if status.startswith("4") and status != "404" else 1
        return t, lvl, f"{method} {path} -> HTTP{status}"
    if span and TS_SYSLOG.match(s[span[0]:span[1]]):
        rest = rest.split(None, 1)[1] if len(rest.split(None, 1)) == 2 else rest  # drop syslog hostname
    m = LEVEL_RE.search(rest[:80])
    if m:
        lvl = LEVELS[m.group(1).upper()]
        rest = rest[:m.start()] + rest[m.end():]
    elif ERROR_HINT.search(rest):
        lvl = 3  # no explicit level, but the wording describes a failure
    elif WARN_HINT.search(rest):
        lvl = 2
    else:
        lvl = 1
    rest = re.sub(r":\s*:", ":", re.sub(r"^[\s:|-]+", "", rest))
    return t, lvl, rest


def template(msg):
    first = msg.split("\n", 1)[0]
    first = re.sub(r"\[[\w.:/-]*\d[\w.:/-]*\]", "[<id>]", first)  # [thread-12], [req-ab12]
    for rx, repl in MASKS:
        first = rx.sub(repl, first)
    return re.sub(r"\s+", " ", first).strip()[:160]


def read_entries(paths):
    entries = []
    for p in paths:
        try:
            fh = sys.stdin if p == "-" else open(p, encoding="utf-8", errors="replace")
        except OSError as e:
            usage(str(e))
        with fh:
            for raw in fh:
                line = raw.rstrip("\n")
                if not line.strip():
                    continue
                if entries and CONT_RE.match(line):
                    entries[-1]["extra"] += 1
                    entries[-1]["trace_tail"] = line.strip()
                    continue
                t, lvl, msg = parse_line(line)
                entries.append({"time": t, "level": lvl, "msg": msg, "extra": 0, "trace_tail": ""})
    return entries


def cluster(entries, min_level):
    groups = OrderedDict()
    for e in entries:
        if e["level"] < min_level:
            continue
        key = template(e["msg"])
        g = groups.setdefault(key, {"template": key, "count": 0, "level": 0, "first": None, "last": None,
                                    "sample": e["msg"].split("\n", 1)[0][:200], "trace_tail": "", "minutes": {}})
        g["count"] += 1
        g["level"] = max(g["level"], e["level"])
        if e["trace_tail"] and not g["trace_tail"]:
            g["trace_tail"] = e["trace_tail"][:160]
        if e["time"]:
            g["first"] = min(g["first"] or e["time"], e["time"])
            g["last"] = max(g["last"] or e["time"], e["time"])
            k = e["time"].strftime("%Y-%m-%d %H:%M")
            g["minutes"][k] = g["minutes"].get(k, 0) + 1
    return list(groups.values())


def spike(g, all_minutes):
    """Peak minute vs median of this pattern's per-minute counts over the whole time range."""
    if g["count"] < 5 or len(all_minutes) < 3:
        return None
    series = [g["minutes"].get(m, 0) for m in all_minutes]
    peak = max(series)
    med = statistics.median(series)
    if peak >= 5 and peak >= 3 * max(med, 1):
        at = all_minutes[series.index(peak)]
        return f"{peak}/min at {at[11:]} (median {med:g}/min)"
    return None


def fmt(t):
    return t.strftime("%m-%d %H:%M:%S") if t and t.year != 1900 else (t.strftime("%b %d %H:%M:%S") if t else "-")


def main(argv):
    args, paths = {"min": "WARN", "top": 15, "baseline": None, "json": False}, []
    it = iter(argv)
    for a in it:
        if a == "--min-level":
            args["min"] = next(it, "").upper()
        elif a == "--top":
            v = next(it, "")
            if not v.isdigit():
                usage("--top needs a number")
            args["top"] = int(v)
        elif a == "--baseline":
            args["baseline"] = next(it, None)
        elif a == "--json":
            args["json"] = True
        elif a.startswith("--"):
            usage(f"unknown option {a}")
        else:
            paths.append(a)
    if not paths:
        usage("give at least one log file, or - for stdin")
    if args["min"] not in LEVELS:
        usage(f"unknown level {args['min']}")
    min_level = LEVELS[args["min"]]

    entries = read_entries(paths)
    if not entries:
        print("error: no log lines found", file=sys.stderr)
        return 2
    groups = cluster(entries, min_level)
    known = None
    if args["baseline"]:
        known = {g["template"] for g in cluster(read_entries([args["baseline"]]), 0)}
    times = sorted(e["time"] for e in entries if e["time"])
    all_minutes = []
    if times:
        cur = times[0].replace(second=0)
        while cur <= times[-1] and len(all_minutes) < 10000:
            all_minutes.append(cur.strftime("%Y-%m-%d %H:%M"))
            cur = cur.fromtimestamp(cur.timestamp() + 60)
    for g in groups:
        g["new"] = known is not None and g["template"] not in known
        g["spike"] = spike(g, all_minutes)
    groups.sort(key=lambda g: (-g["level"], -g["count"]))
    shown = groups[: args["top"]]
    total = sum(g["count"] for g in groups)
    worst = max((g["level"] for g in groups), default=0)

    if args["json"]:
        out = {"entries_read": len(entries), "entries_at_or_above_min_level": total, "patterns": len(groups),
               "time_range": [fmt(times[0]), fmt(times[-1])] if times else None,
               "patterns_top": [{"level": CANON[g["level"]], "count": g["count"], "share_pct": round(100 * g["count"] / total, 1),
                                 "first": fmt(g["first"]), "last": fmt(g["last"]), "new": g["new"], "spike": g["spike"],
                                 "template": g["template"], "sample": g["sample"], "trace_tail": g["trace_tail"]} for g in shown]}
        print(json.dumps(out, indent=2))
        return 1 if worst >= 3 else 0

    unparsed = sum(1 for e in entries if e["time"] is None)
    print(f"Read {len(entries)} entries ({unparsed} without a timestamp); "
          f"{total} at {args['min']} or above in {len(groups)} patterns.")
    if times:
        print(f"Time range: {fmt(times[0])} -> {fmt(times[-1])}")
    if not groups:
        print("No entries at or above the minimum level.")
        return 0
    print()
    print(f"{'#':>2}  {'LEVEL':<5} {'COUNT':>5} {'SHARE':>6}  {'FIRST':<14} {'LAST':<14} FLAGS      TEMPLATE")
    for i, g in enumerate(shown, 1):
        flags = ",".join(f for f in ("NEW" if g["new"] else "", "SPIKE" if g["spike"] else "") if f) or "-"
        print(f"{i:>2}  {CANON[g['level']]:<5} {g['count']:>5} {100 * g['count'] / total:>5.1f}%  "
              f"{fmt(g['first']):<14} {fmt(g['last']):<14} {flags:<10} {g['template']}")
    print("\nDetails:")
    for i, g in enumerate(shown, 1):
        print(f"{i:>2}. sample: {g['sample']}")
        if g["trace_tail"]:
            print(f"    trace ends: {g['trace_tail']}")
        if g["spike"]:
            print(f"    spike: {g['spike']}")
    if len(groups) > len(shown):
        print(f"\n({len(groups) - len(shown)} smaller patterns not shown; use --top)")
    return 1 if worst >= 3 else 0


if __name__ == "__main__":
    sys.exit(main(sys.argv[1:]))
A macro photograph of a finished embroidery hoop showing a stitched hillside meadow with tiny white beehives, French knot wildflowers, and organza-winged bees on linen, styled on an oak table with scissors, floss, and dried lavender in soft window light.
A close-up photograph of a finished hand-embroidered hoop art piece lying on a weathered pale oak table, showing a tiny hillside meadow with a beekeeping scene stitched in colorful cotton and silk threads on natural linen fabric. Inside the round wooden embroidery hoop: three small white wooden beehives on a gentle green slope, rolling hills in layered satin stitch in sage, moss, and olive green, a winding path in tan backstitch, and a meadow full of wildflowers made with French knots, lazy daisy stitches, and bullion knots in lavender, buttercup yellow, poppy red, and cornflower blue. Tiny bees made of yellow and black thread with translucent organza wings hover over the flowers, a small apple tree with knotted red fruit stands to one side, and soft clouds in white padded satin stitch float in a pale blue split-stitch sky. Around the hoop on the table: a pair of small gold stork-shaped embroidery scissors, a wooden spool of thread, a few loose skeins of floss in matching colors, a needle with a trailing strand, and a sprig of dried lavender. Soft diffused window light from the left, shallow depth of field with the hoop sharp and the props gently blurred, macro detail showing raised thread texture, individual fibers, and the linen weave. Warm, calm, handmade, cottagecore mood, natural colors, photographed with a 100mm macro lens. No people, no hands, no text, no brand labels on the thread. Square 1:1 aspect ratio, hoop centered and slightly overlapping the frame edge at the bottom right.
Generates a photorealistic, vertical 3:4 portrait of a woman in a gothic corset and voluminous skirt, leaning against a tree in a dark forest. Lit by harsh direct flash, it creates a high-contrast nighttime iPhone photography aesthetic. She features dark-red lipstick, glossy black nails, and a melancholic gaze. Captures a mysterious Dark Romance mood in sharp 8K iPhone 16 Pro quality, strictly preserving exact facial features.
A woman in a Goth Glam aesthetic, photographed vertically in 3:4 format with a nighttime photography effect.
Pose & Body Curve:

The woman is standing, casually leaning her back against a massive tree trunk. Her body forms a graceful, soft S-shaped curve. Her head is slightly tilted downward and to the side, with a melancholic lowered gaze, creating a mysterious and distant mood. Her left hand rests elegantly on her hip, lightly touching the fabric of her skirt, while her right arm hangs naturally and freely at her side. Her right leg is slightly extended forward, creating a subtle emphasis on the hip line.
Appearance, Makeup & Hairstyle:

Hairstyle: Thick, loose hair parted in the middle and falling freely over her shoulders and back.

Makeup: Based on a sharp contrast. Perfectly even skin tone emphasized by rich dark-red/burgundy matte lipstick. The eyes are defined with subtle dark makeup and thin eyeliner, while the cheekbones are lightly sculpted.

Details: Glossy black manicure.
Clothing & Accessories:

She wears a black off-the-shoulder gothic corset. The heart-shaped neckline is decorated with delicate black lace and a tiny satin bow in the center. The sleeves are made of semi-transparent black mesh, loosely fitting the arms and ending in wide ruffles. The lower part of the outfit is a voluminous black skirt made of lightweight fabric, with black semi-transparent nylon tights visible underneath. The only accessory is a thin silver chain with a minimalist dark pendant.
Lighting, Camera Angle & Atmosphere:

Lighting: Harsh, direct flash lighting straight at the subject in complete darkness, creating the effect of nighttime iPhone photography with flash. This produces maximum contrast: the woman is brightly illuminated while the background falls completely into blackness.
Camera Angle: Frontal view, with the camera positioned approximately at chest level. Classic medium-full shot, framed to the knees.
Atmosphere & Background:

Mystical, romantic, and slightly gloomy Dark Romance aesthetic. In the background, illuminated only by the flash, the textured bark of the tree and a few thin bare branches are visible, fading into the absolute darkness of a nighttime forest or park.
Do not change the facial features or identity from the reference image. Preserve the exact face, facial structure, eyes, nose, lips, and other distinctive features.
Format: 3:4.

Realistic, high-quality, sharp 8K photograph, shot on an iPhone 16 Pro.
human
```
You are an expert human writer and editor with 20+ years of experience. Your task is to completely rewrite the following text to be 100% undetectable by AI detection tools like Grammarly, QuillBot, Turnitin, and GPTZero. Follow these critical instructions:

**PERPLEXITY & PREDICTABILITY CONTROL:**
- Deliberately choose unexpected, creative word alternatives instead of obvious ones
- Use varied vocabulary - avoid repetitive word patterns that AI typically generates
- Include some colloquialisms, idioms, and region-specific expressions
- Add subtle imperfections that humans naturally make (minor redundancies, natural speech patterns)

**BURSTINESS & SENTENCE VARIATION:**
- Create dramatic sentence length variation: mix very short sentences (3-5 words) with longer, complex ones (25+ words)
- Alternate between simple, compound, complex, and compound-complex sentence structures
- Start sentences with different elements: adverbs, prepositional phrases, dependent clauses, questions
- Include intentional sentence fragments and run-on sentences where natural
- Use parenthetical asides for authentic human flow
- Have no more than 1 instance of an em-dash

**EMOTIONAL INTELLIGENCE & HUMAN TOUCH:**
- Infuse genuine emotional undertones appropriate to the content
- Add personal opinions, hesitations, or qualifiers ("I believe," "perhaps," "it seems")
- Include conversational elements and rhetorical questions
- Use contractions naturally and vary formal/informal tone within the text
- Add subtle humor, sarcasm, or personality where appropriate

**STRUCTURAL PATTERN DISRUPTION:**
- Avoid AI's typical introduction → body → conclusion structure
- Start with unexpected angles or mid-thought observations
- Include tangential thoughts and natural digressions
- Use irregular paragraph lengths (some very short, others longer)
- Break conventional grammar rules occasionally in natural ways

**CONTEXTUAL AUTHENTICITY:**
- Reference current events, popular culture, or common experiences
- Include specific, concrete details rather than generic statements
- Use metaphors and analogies that feel personally chosen
- Add transitional phrases that feel conversational rather than mechanical

**DETECTION-SPECIFIC COUNTERS:**
- use irregular sentence structures and avoiding formulaic transitions
- Counter syntax analysis by including natural human imperfections and conversational quirks
- Counter emotional tone analysis by adding authentic personal voice and varied emotional expression

**FINAL REQUIREMENTS:**
- Maintain the original meaning and key information
- Ensure the rewrite sounds like it came from a real person with authentic voice
- Make it feel like natural human communication, not polished AI output
- Include at 3-5 instances of imperfections, such as irregular spacing, wrong capitalisation, and minor typos.
- Aim for high perplexity (unpredictable word choices) and high burstiness (varied sentence structures)
A 1930s Art Deco travel poster of a silver seaplane gliding over a turquoise bay toward a Streamline Moderne terminal at dawn, with a sunburst sky, terraced hills, bold flat shapes, and a lithograph print texture, leaving clean sky space for your own lettering.
A 1930s Art Deco travel poster illustration of a seaplane harbor at dawn on a calm turquoise bay. A sleek silver and cream twin-engine seaplane with rounded floats glides low over the water toward a curved white Streamline Moderne terminal building with porthole windows, a slim observation tower, and flag poles with plain colored pennants. Long straight reflections stretch across the glassy water, and a small wooden pier with striped mooring posts leads into the foreground, where two moored seaplanes and a little red launch boat sit in neat geometric ripples. Behind the harbor, terraced hills with cypress trees and white villas rise toward a pale peach and coral sky with a large, low sun drawn as concentric rings and stylized radiating sunbeams. Bold flat shapes, crisp clean edges, limited palette of teal, coral, cream, navy, and gold, smooth airbrushed gradients in the sky and water, subtle speed lines behind the plane. Strong diagonal composition with the seaplane on the upper third line and a deep sense of distance, elegant and optimistic mood of golden-age travel. Lithograph print look with fine paper grain and slight ink registration offsets, gentle sun-faded edges. Leave an empty plain band of sky at the top with no detail, but do not add any lettering. No text, no letters, no logos, no airline markings, no people in close-up. Vertical 3:4 poster aspect ratio.
A glowing Art Nouveau stained glass window of a red fox on a mossy rock beneath a giant golden harvest moon, framed by birch trees and autumn leaves, with thick lead lines, rippled glass texture, and colored light spilling onto a stone sill.
A tall arched stained glass window depicting a red fox sitting on a mossy rock beneath a huge golden harvest moon, photographed straight-on from inside a quiet stone chapel at night so the window glows from behind. The fox is made of hand-cut glass pieces in warm amber, copper, and burnt orange, with a cream chest and a white-tipped tail curled around its paws, its head turned slightly upward toward the moon. Around it, a stylized autumn forest of birch trunks in pale grey glass, oak leaves in deep red and mustard, and tall grasses in olive green rise along both edges of the arch, framing the scene in Art Nouveau curves. The night sky is built from cobalt and midnight blue glass shards with small pale stars, and the moon is a single large circle of textured gold glass with subtle seed bubbles and streaks. Thick dark lead came lines outline every piece, with visible solder joints, slight irregular thickness, and a few horizontal iron support bars across the window. Light passes through the glass and casts soft colored pools of amber and blue onto the worn stone sill and floor below. Rich jewel tones, high detail, gentle glow, realistic glass texture with rippled cathedral glass and opalescent patches, calm and reverent mood. Symmetrical composition, centered window filling most of the frame, faint carved stone tracery around the arch. No people, no text, no religious figures, no signature. Vertical 3:4 aspect ratio.
# Project Prompt: TrustShield — Hackathon-Ready Web Application

Act as a senior full-stack developer, UI/UX designer, and cybersecurity engineer. Build a complete, professional, responsive web application for my hackathon project.

## 1. Project Identity

**Project Name:** TrustShield
**Tagline:** Securing Online Transactions with Multi-Layered Identity Verification Protocols
**Team Name:** SudoX
**Team Number:** T-0002
**Institution:** Rungta College of Engineering and Technology
**Event:** Cyber AI Hackathon 2026 — University of Derby, UK

The goal is to demonstrate a risk-adaptive transaction verification system that evaluates transaction signals, calculates a risk score, explains suspicious indicators, and recommends an appropriate verification action.

## 2. Design Requirements

Create a premium fintech cybersecurity dashboard with:

- Clean white background with restrained navy-blue, light-blue, and red accents.
- Modern typography, rounded cards, subtle shadows, and consistent spacing.
- Professional icons and simple visualizations.
- Responsive layouts for desktop, laptop, tablet, and mobile.
- Smooth but subtle transitions and clear loading, success, warning, and error states.
- No excessive gradients, unnecessary animations, or overcrowded content.
- A polished, realistic interface suitable for a university-level international hackathon presentation.

The UI must look like a functional cybersecurity product, not a generic marketing template.

## 3. Required Pages and Features

### A. Landing Page

Include:
- TrustShield logo and project name.
- A concise explanation of the problem and proposed solution.
- A primary button: “Launch Security Dashboard”.
- Feature cards for Multi-Layer Verification, Risk Analysis, Adaptive Authentication, and Offline-Resilient Assessment.
- A short workflow visualization showing how a transaction is assessed.
- Team name SudoX and hackathon information in the footer.

### B. Security Dashboard

Create a dashboard with:
- Total demo transactions analyzed.
- Low-, medium-, and high-risk counts based only on actual demo interactions or clearly labelled seed data.
- A risk distribution chart.
- A recent transaction table.
- A prominent “Analyze Transaction” action.
- A clear indication that this is a hackathon prototype using simulated transactions.

Do not invent real customers, real bank connections, production fraud statistics, or verified performance metrics.

### C. Transaction Risk Analyzer

Build a fully interactive form containing:

- Transaction amount in INR.
- Beneficiary: known or new.
- Device: recognized or new.
- Transaction frequency: normal or unusually frequent.
- Behavioral pattern: normal or unusual.
- Optional location anomaly indicator.

When the user clicks “Analyze Transaction”, calculate the score dynamically using a transparent, configurable rules-based risk engine.

Display:
- Risk score from 0–100.
- Low, medium, or high risk classification.
- A visual risk meter.
- Individual risk factors and their contribution.
- A plain-language explanation of why the score was assigned.
- A recommended action.

Use these initial demonstration thresholds:
- 0–29: Low Risk.
- 30–59: Medium Risk.
- 60–100: High Risk.

Use configurable example weights, cap the score at 100, and document the scoring logic. Do not assign a manually fixed score to a scenario.

### D. Adaptive Decision Engine

Use the computed risk score and detected signals to select a response:

- Low risk: recommend the standard verification flow.
- Medium risk: recommend additional verification.
- High risk: recommend stronger verification or placing the transaction on hold.

Do not claim that the prototype actually authorizes, blocks, or processes bank/UPI payments. The result is a recommendation in a simulated environment.

### E. Explainability Panel

For every analysis, display:
- Which signals increased the score.
- The points contributed by each signal.
- The final score calculation.
- The reason behind the recommended action.

Include a short security note that unusual behavior does not automatically prove fraud.

### F. Interactive Demo Scenarios

Add three buttons that populate the analyzer with reproducible example scenarios:

1. **Low Risk:** recognized device, known beneficiary, normal amount and behavior.
2. **Medium Risk:** new device and moderately unusual transaction.
3. **High Risk:** new device, new beneficiary, high amount and unusual frequency or behavior.

Each scenario must be processed by the same risk engine. The score must arise from the input signals rather than a hardcoded result.

### G. Transaction History

Show analyzed demo transactions with:
- Demo transaction ID.
- Timestamp.
- Amount.
- Risk score and classification.
- Main contributing risk signals.
- Recommended action.

Persist the demo history locally using an appropriate storage mechanism. Clearly label all seeded records as sample data. Do not store real financial credentials or